iTranslated by AI
Exploring Kubernetes Multi-Cluster Management with Karmada



What is Karmada
Karmada is an open-source project for achieving k8s multi-cluster management. It currently has about 4k GitHub stars and is a CNCF Incubating project.
Originally developed by HUAWEI Cloud, the cloud division of the well-known smartphone manufacturer Huawei, it was donated to the CNCF in September 2021. An article was also posted on the CNCF blog in December 2023.
Karmada's architecture achieves multi-cluster management by configuring a Karmada control plane to manage multiple clusters, deploying resources to those managed clusters, and performing pod scheduling.
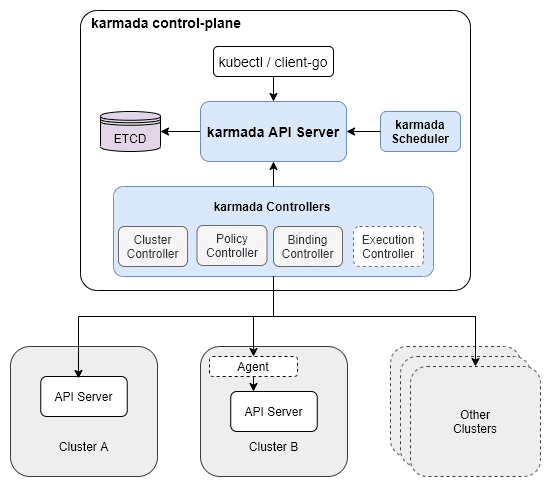
Karmada architecture. Quoted from https://karmada.io/docs/core-concepts/architecture
Karmada's main features are summarized in Key Features.
- Multi-cloud and Multi-cluster Management
- Communication from the Karmada control plane to managed clusters uses either kube-apiserver or a Karmada agent, so it is not restricted to specific cloud providers. Therefore, it is possible to collectively manage AWS, Azure, and on-premises k8s clusters.
- Deployment to Multi-clusters
- Resources can be deployed to managed clusters simultaneously, and properties can be dynamically changed according to the destination cluster using a CRD called Override Policy.
- Advanced Scheduling and Failover across Clusters
- By applying Affinity, Splitting/Rebalancing, etc., between clusters, pod placement strategies in regular k8s clusters and failover during node failures can be realized at the cluster level.
- Cross-cluster Service Discovery and AutoScaling
- By using external features that enable cross-cluster networking, such as Submariner, cross-cluster service discovery and auto-scaling can be achieved.
Note that while Kubernetes Federation V2 (kubefed) existed for multi-cluster management in k8s, Karmada seems to be developed as its successor.
Notice: this project is developed in continuation of Kubernetes Federation v1 and v2. Some basic concepts are inherited from these two versions.
Setting up Karmada
Let's actually prepare a Karmada control plane and managed clusters to experience what kind of multi-cluster management is possible.
Environment
To verify the multi-cluster management behavior with Karmada, we will prepare three k8s clusters: one for the Karmada control plane and the remaining two as clusters managed by Karmada. Each cluster will have a simple configuration of one control-plane node and one worker node.
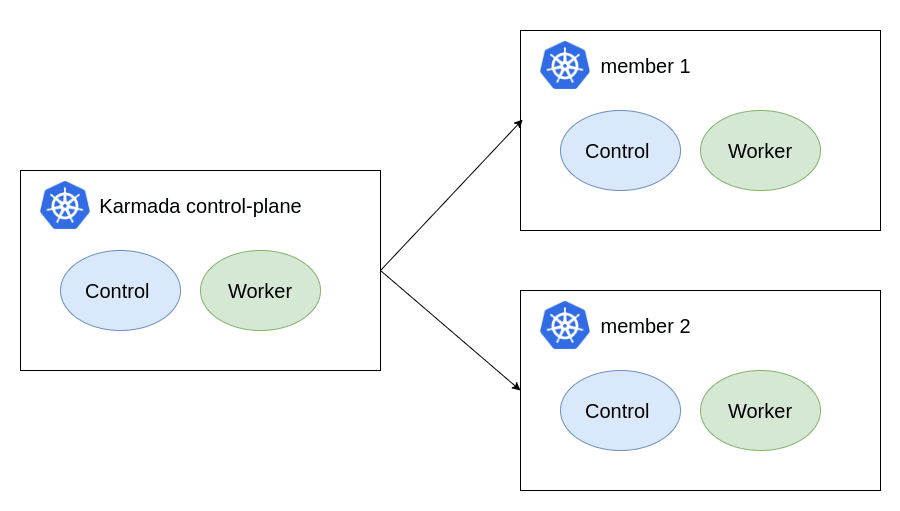
Configuration of verification clusters
Installing Karmada
As described in the installation documentation, Karmada can be installed using various methods, including setup scripts, Helm, and an operator. Here, we will build the environment by installing the Karmada operator and then creating a Karmada instance via a CRD.
Installing the Operator
Operator Installation Steps
The operator can be installed using Helm, but since it is not registered in a chart repository, the procedure involves cloning the git repository containing the chart and installing it from the local path. First, perform the clone.
git clone https://github.com/karmada-io/karmada.git
cd karmada
You can then install it using helm install. However, as I encountered errors that prevented a successful installation with the current latest version, I will use version v1.10.0 this time. To change the operator version, modify the image tag in the operator's chart values as follows:
operator:
  image:
    registry: docker.io
      repository: karmada/karmada-operator
-      tag: latest
+      tag: v1.10.0
Run helm install:
helm install karmada-operator -n karmada-system --create-namespace --dependency-update ./charts/karmada-operator --debug
This creates an operator pod in the karmada-system namespace. Next, create a secret containing the kubeconfig content to be used during installation.
kubectl create secret generic my-kubeconfig --from-file=$HOME/.kube/config -n karmada-system
After the operator starts, you can build the necessary components for the Karmada control plane by creating a CRD called a Karmada Instance.
kubectl create namespace test
kubectl apply -f - <<EOF
apiVersion: operator.karmada.io/v1alpha1
kind: Karmada
metadata:
  name: karmada-demo
  namespace: test
EOF
However, to align each Karmada component with v1.10.0, we will rewrite the image tags for each component to v1.10.0 based on the sample Karmada Instance manifest at https://github.com/karmada-io/karmada/blob/master/operator/config/samples/karmada.yaml.
apiVersion: operator.karmada.io/v1alpha1
kind: Karmada
metadata:
  name: karmada
  namespace: karmada
spec:
  components:
    etcd:
      local:
        imageRepository: registry.k8s.io/etcd
        imageTag: 3.5.13-0
        replicas: 1
        volumeData:
          # hostPath:
          #   type: DirectoryOrCreate
          #   path: /var/lib/karmada/etcd/karmada-demo
          volumeClaim:
            metadata:
              name: etcd-data
            spec:
              accessModes:
                - ReadWriteOnce
              resources:
                requests:
                  storage: 3Gi
    karmadaAPIServer:
      imageRepository: registry.k8s.io/kube-apiserver
      imageTag: v1.28.9
      replicas: 1
      serviceType: NodePort
      serviceSubnet: 10.96.0.0/12
    karmadaAggregatedAPIServer:
      imageRepository: docker.io/karmada/karmada-aggregated-apiserver
      imageTag: v1.10.0
      replicas: 1
    karmadaControllerManager:
      imageRepository: docker.io/karmada/karmada-controller-manager
      imageTag: v1.10.0
      replicas: 1
    karmadaScheduler:
      imageRepository: docker.io/karmada/karmada-scheduler
      imageTag: v1.10.0
      replicas: 1
    karmadaWebhook:
      imageRepository: docker.io/karmada/karmada-webhook
      imageTag: v1.10.0
      replicas: 1
    kubeControllerManager:
      imageRepository: registry.k8s.io/kube-controller-manager
      imageTag: v1.28.9
      replicas: 1
    karmadaMetricsAdapter:
      imageRepository: docker.io/karmada/karmada-metrics-adapter
      imageTag: v1.10.0
      replicas: 2
    # karmadaSearch: # the component `Karmadasearch` is not installed by default, if you need to install it, uncomment it and note the formatting
      # imageRepository: docker.io/karmada/karmada-search
      # imageTag: v1.10.0
      # replicas: 1
    # karmadaDescheduler: # the component `KarmadaDescheduler` is not installed by default, if you need to install it, uncomment it and note the formatting
      # imageRepository: docker.io/karmada/karmada-descheduler
      # imageTag: v1.10.0
      # replicas: 1
  hostCluster:
    networking:
      dnsDomain: cluster.local
Deploy this.
kubectl create ns karmada
kubectl apply -f karmada.yml
Once the deployment is successfully completed, the pods constituting the Karmada control plane will start.
$ kubectl get pod
NAME                                               READY   STATUS    RESTARTS   AGE
karmada-aggregated-apiserver-58b4558c96-ld8dq      1/1     Running   0          2m54s
karmada-apiserver-86648f5476-g6kn9                 1/1     Running   0          3m5s
karmada-controller-manager-754496f5bf-xnr68        1/1     Running   0          2m50s
karmada-etcd-0                                     1/1     Running   0          3m6s
karmada-kube-controller-manager-74f76db4c8-9fdg5   1/1     Running   0          2m50s
karmada-metrics-adapter-69cc7c74f5-mpml9           1/1     Running   0          2m50s
karmada-metrics-adapter-69cc7c74f5-zt7st           1/1     Running   0          2m50s
karmada-scheduler-76bb67cb4d-ptvk7                 1/1     Running   0          2m50s
karmada-webhook-7f78445f89-s42l6                   1/1     Running   0          2m50s
Also, since operations related to Karmada are basically performed using the dedicated Karmada CLI (karmadactl), install it as well. There are several installation methods, but if you are using krew, it is easiest to install as follows:
kubectl krew install karmada
About karmada-apiserver
Once the construction of the Karmada control plane is complete, a secret named karmada-admin-config is created in the specified namespace. Its content is a configuration file for communicating with the karmada-apiserver. It is basically the same as a kubeconfig, but there are differences such as the server pointing to the karmada-apiserver (the nodePort of the karmada-apiserver in the example below) and the certificate-related information being the authentication credentials from when Karmada was built.
$ k get secrets karmada-admin-config -o yaml | yq -r ".data.kubeconfig"  | base64 -d
apiVersion: v1
clusters:
- cluster:
    certificate-authority-data:
    ...
    server: https://10.0.0.40:30238
  name: karmada-apiserver

contexts:
- context:
    cluster: karmada-apiserver
    user: karmada-admin
  name: karmada-admin@karmada-apiserver
current-context: karmada-admin@karmada-apiserver
kind: Config
preferences: {}
users:
- name: karmada-admin
  user:
    client-certificate-data:
    ...
    client-key-data:
    ...
In the documentation, where --kubeconfig=<karmada kubeconfig> is written, it basically refers to this config for the karmada-apiserver. Since there are many situations where you will switch between the default kubeconfig and the Karmada kubeconfig in subsequent tasks, it is convenient to copy the content from the secret and save it to a file on the host side to facilitate access.
Let's briefly touch upon the karmada-apiserver here. In the Karmada control plane, the architecture is designed so that the karmada-apiserver handles Karmada-related APIs, just like the kube-apiserver in a regular k8s cluster. Furthermore, it also maintains compatibility with the regular Kubernetes API, as described below:
Karmada API server directly uses the implementation of kube-apiserver from Kubernetes, which is the reason why Karmada is naturally compatible with Kubernetes API. That makes integration with the Kubernetes ecosystem very simple for Karmada, such as allowing users to use kubectl to operate Karmada, integrating with ArgoCD, integrating with Flux and so on.
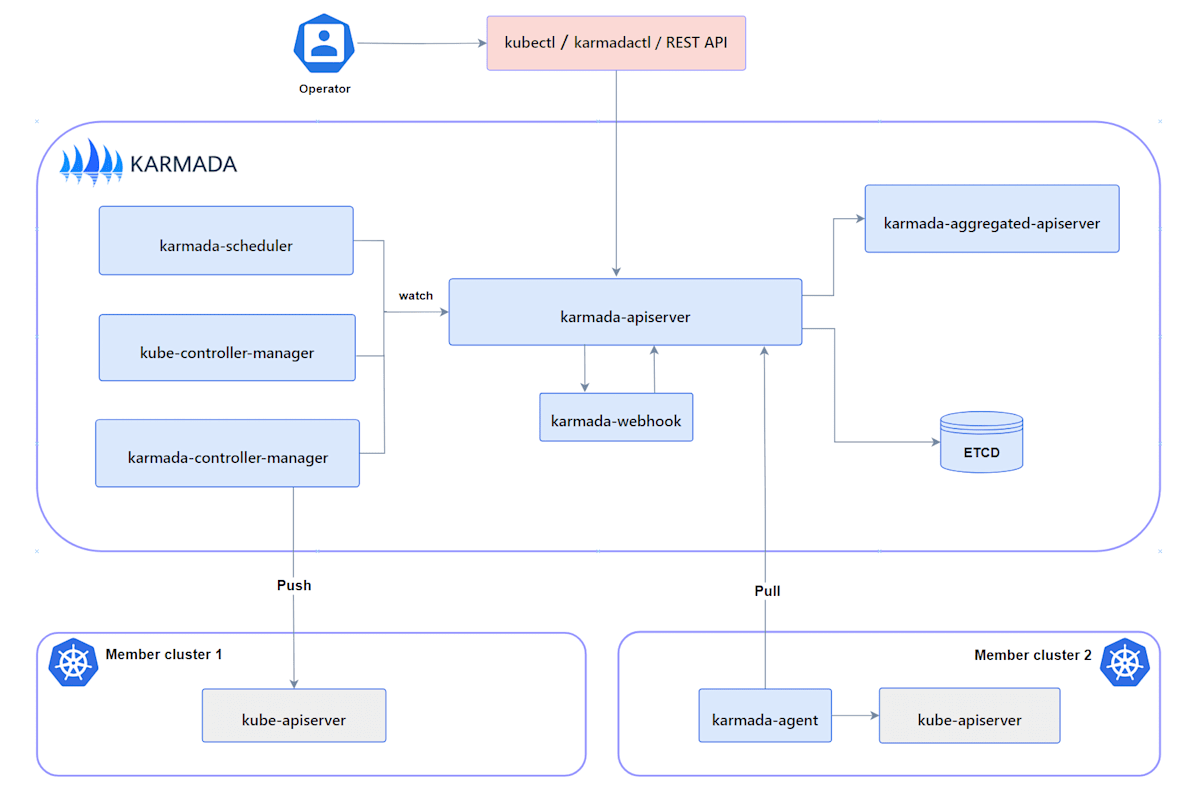
karmada-apiserver plays the role of kube-apiserver in a regular k8s cluster. Quoted from https://karmada.io/docs/core-concepts/components#karmada-apiserver
When performing operations such as deployment to clusters managed by Karmada using the Karmada API, it is necessary to communicate with the karmada-apiserver, which is why a kubeconfig for the karmada-apiserver is required as mentioned above. Also, while the architecture diagram shows data being saved to etcd, this is saved to a pod created within the Karmada control plane, which is a separate storage location from the etcd that exists by default in the k8s cluster. Therefore, care should be taken as the pods displayed will differ when switching contexts between the kubeconfig and the Karmada kubeconfig.
Registering Clusters
Now that the Karmada control plane construction is complete, the next step is to register the clusters to be managed. Two Cluster Modes are provided for cluster registration and management: Push mode and Pull mode. https://karmada.io/docs/userguide/clustermanager/cluster-registration
- Push mode
- The Karmada control plane communicates directly with the
kube-apiserveron the managed k8s cluster.
- The Karmada control plane communicates directly with the
- Pull mode
- A
karmada-agentis installed on the managed k8s cluster, and thekarmada-agentcommunicates with the Karmada control plane to perform registration and management.
- A
Cluster registration is possible using either method, but the Pull mode requires additional configuration to enable communication between the Karmada control plane and the external cluster. Since this involves more steps and is somewhat tedious, we will register the clusters using the Push mode here.
Cluster registration can be performed using the karmada join command as described in the documentation, but a kubeconfig for accessing the kube-apiserver of the target cluster is required as <member1 kubeconfig>, so copy the content to your working environment.
In this case, we use the control-plane node of the Karmada cluster as the working environment and save the Karmada kubeconfig and the target cluster's kubeconfig at the following paths on the node:
- Karmada kubeconfig:
~/.kube/karmada.config - Target cluster's kubeconfig:
~/.kube/sub1.config
The command format for adding a cluster to the management targets is as follows:
kubectl karmada join <cluster_name> --kubeconfig=<karmada kubeconfig> --cluster-kubeconfig=<member1 kubeconfig>
This time, we will register the target cluster with the name member1. If joined successfully is displayed after running the command, registration was successful.
$ kubectl karmada join member1 --kubeconfig=/home/ubuntu/.kube/karmada.config --cluster-kubeconfig=/home/ubuntu/.kube/sub1.config  -v 5
I0615 06:13:22.627225  312437 join.go:158] Joining cluster. cluster name: member1
I0615 06:13:22.627268  312437 join.go:159] Joining cluster. cluster namespace: karmada-cluster
I0615 06:13:22.628820  312437 join.go:183] Joining cluster config. endpoint: https://10.0.0.30:6443
cluster(member1) is joined successfully
When performing operations related to the Karmada API, you generally need to specify the Karmada config with --kubeconfig. Since specifying it every time is cumbersome, it's easier to set it in export KUBECONFIG (though you could also add it to a context and switch with kubectx).
export KUBECONFIG=/home/ubuntu/.kube/karmada.config
In the same way, copy the kubeconfig of another cluster as ~/.kube/sub2.config to the node and register it as member2.
$ kubectl karmada join member2 --kubeconfig=/home/ubuntu/.kube/karmada.config --cluster-kubeconfig=/home/ubuntu/.kube/sub2.config -v 5
With this, two clusters have been added as managed targets. You can check the registration status of the clusters with kubectl get clusters.
$ k get clusters
NAME      VERSION   MODE   READY   AGE
member1   v1.29.6   Push   True    2d6h
member2   v1.29.6   Push   True    2d6h
Deploying Resources to Multiple Clusters
When deploying resources to multiple clusters in Karmada, it is achieved using a CRD called PropagationPolicy. To summarize the procedure, it consists of the following simple steps:
- Define the resource you want to deploy and create it.
- Specify the above resource in a
PropagationPolicyand deploy it to the target clusters.
There is a simple tutorial in Resource Propagating, so let's try it out.
First, create a manifest for the nginx deployment, which is the resource to be deployed. There are no Karmada-specific descriptions for this, and it can be created as a regular k8s manifest.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: nginx
  namespace: default
  labels:
    app: nginx
spec:
  replicas: 2
  selector:
    matchLabels:
      app: nginx
  template:
    metadata:
      labels:
        app: nginx
    spec:
      containers:
      - name: nginx
        image: nginx
        ports:
        - containerPort: 80
Deploy this to the Karmada control plane side.
$ export KUBECONFIG=/home/ubuntu/.kube/karmada.config
$ k apply -f nginx.yml
At this point, pods are not created in either the Karmada cluster or the member clusters. On the Karmada side, the deployment resource itself has been created, but the number of replicas is set to 0.
$ k get deployments.apps
NAME    READY   UP-TO-DATE   AVAILABLE   AGE
nginx   0/2     0            0           95s
Next, create a PropagationPolicy CRD to deploy the above deployment to the member clusters.
- Specify the resource to be deployed in
resourceSelectors. Here, you specify thekindandnameof the target resource. - In
namespace, specify the namespace where the resource should be created in the target clusters. - The destination clusters are specified in
placement. You can specify cluster names directly or use a label selector, similar to pod placement.
apiVersion: policy.karmada.io/v1alpha1
kind: PropagationPolicy
metadata:
  name: nginx # The default namespace is `default`.
  namespace: default
spec:
  resourceSelectors:
    - apiVersion: apps/v1
      kind: Deployment
      name: nginx # If no namespace is specified, the namespace is inherited from the parent object scope.
      namespace: default
  placement:
    clusterAffinity:
      clusterNames:
        - member1
        - member2
Deploy.
$ k apply -f propagate.yml
propagationpolicy.policy.karmada.io/nginx created
Resources deployed to managed clusters can be retrieved using kubectl karmada get [resource], just like regular kubectl. While this is how it should normally be retrieved, an error occurred when I tried it.
$ k karmada get pod
cluster(member2) is inaccessible, please check authorization or network
cluster(member1) is inaccessible, please check authorization or network
Karmada commands allow you to set the detail level using -v, just like kubectl. If an error occurs, it is recommended to specify -v 5 or higher, as there is too little information without it.
Below is the result of running with -v 10.
I0621 08:02:46.549252 2522618 round_trippers.go:553] GET https://10.0.0.40:30238/apis/cluster.karmada.io/v1alpha1/clusters/member1/proxy/api 403 Forbidden in 7 milliseconds
I0621 08:02:46.549351 2522618 round_trippers.go:570] HTTP Statistics: GetConnection 0 ms ServerProcessing 7 ms Duration 7 ms
I0621 08:02:46.549363 2522618 round_trippers.go:577] Response Headers:
I0621 08:02:46.549370 2522618 round_trippers.go:580]     Cache-Control: no-cache, private
I0621 08:02:46.549375 2522618 round_trippers.go:580]     Cache-Control: no-cache, private
I0621 08:02:46.549380 2522618 round_trippers.go:580]     Cache-Control: no-cache, private
I0621 08:02:46.549385 2522618 round_trippers.go:580]     Content-Type: application/json
I0621 08:02:46.549390 2522618 round_trippers.go:580]     Date: Fri, 21 Jun 2024 08:02:46 GMT
I0621 08:02:46.549448 2522618 round_trippers.go:580]     Content-Length: 344
I0621 08:02:46.549513 2522618 round_trippers.go:580]     Audit-Id: a2ef0b6e-420d-44dd-8d2b-63d349e3922d
I0621 08:02:46.549574 2522618 round_trippers.go:580]     Audit-Id: a2ef0b6e-420d-44dd-8d2b-63d349e3922d
I0621 08:02:46.549633 2522618 round_trippers.go:580]     Audit-Id: a2ef0b6e-420d-44dd-8d2b-63d349e3922d
I0621 08:02:46.549692 2522618 round_trippers.go:580]     X-Content-Type-Options: nosniff
I0621 08:02:46.549769 2522618 request.go:1212] Response Body: {"kind":"Status","apiVersion":"v1","metadata":{},"status":"Failure","message":"users \"system:admin\" is forbidden: User \"system:serviceaccount:karmada-cluster:karmada-impersonator\" cannot impersonate resource \"users\" in API group \"\" at the cluster scope","reason":"Forbidden","details":{"name":"system:admin","kind":"users"},"code":403}
It seems that a 403 error occurs when retrieving information from member clusters, and as indicated in the Response Body, the system:serviceaccount:karmada-cluster:karmada-impersonator ServiceAccount is lacking permission for system:admin.
Checking the SA and ClusterRole on the member1 cluster side indeed confirms that the permissions are insufficient.
$ k get clusterrole karmada-impersonator -o yaml
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRole
metadata:
  annotations:
    resourcetemplate.karmada.io/managed-annotations: resourcetemplate.karmada.io/managed-annotations,resourcetemplate.karmada.io/managed-labels,resourcetemplate.karmada.io/uid,work.karmada.io/name,work.karmada.io/namespace
    resourcetemplate.karmada.io/managed-labels: karmada.io/managed,work.karmada.io/permanent-id
    resourcetemplate.karmada.io/uid: ""
    work.karmada.io/name: karmada-impersonator-7cbb6bd5c9
    work.karmada.io/namespace: karmada-es-member1
  creationTimestamp: "2024-06-21T08:00:21Z"
  labels:
    karmada.io/managed: "true"
    work.karmada.io/permanent-id: ae904d66-7c0f-4347-ba4d-a65c26e25688
  name: karmada-impersonator
  resourceVersion: "2073"
  uid: d44d0d8e-a765-49b7-b7a9-b18032939361
rules:
- apiGroups:
  - ""
  resourceNames:
  - system:kube-controller-manager
  resources:
  - users
  verbs:
  - impersonate
- apiGroups:
  - ""
  resourceNames:
  - generic-garbage-collector
  - namespace-controller
  - resourcequota-controller
  resources:
  - serviceaccounts
  verbs:
  - impersonate
- apiGroups:
  - ""
  resourceNames:
  - system:masters
  resources:
  - groups
  verbs:
  - impersonate
While it's unclear why it's insufficient, since this is for verification, I will directly edit the ClusterRole to add the permission. However, because resources are managed by Karmada internally, even if you execute edit, the changes won't persist unless you remove the karmada.io/managed: "true" label.
$ k edit clusterrole karmada-impersonator

metadata:
  labels:
-    karmada.io/managed: "true"
    work.karmada.io/permanent-id: ae904d66-7c0f-4347-ba4d-a65c26e25688
  name: karmada-impersonator
  resourceVersion: "3496"
  uid: d44d0d8e-a765-49b7-b7a9-b18032939361
rules:
  - apiGroups:
    - ""
    resourceNames:
    - system:kube-controller-manager
+   - system:admin
    resources:
    - users
    verbs:
    - impersonate
By applying the above fix to both the member1 and member2 clusters, communication becomes possible, and you can see the pods deployed in each cluster. You can confirm that two pods each are deployed on the worker nodes of member1 and member2, as specified in the manifest's replica count.
$ k karmada get pod -o wide
NAME                     CLUSTER   READY   STATUS    RESTARTS   AGE    IP             NODE      NOMINATED NODE   READINESS GATES   ADOPTION
nginx-77d8468669-2d4tr   member1   1/1     Running   0          4d3h   10.244.1.122   k8s-w1    <none>           <none>            N
nginx-77d8468669-c2v8v   member1   1/1     Running   0          4d3h   10.244.1.121   k8s-w1    <none>           <none>            N
nginx-86dcfdf4c6-kzrd5   member2   1/1     Running   0          4d3h   10.244.1.8     sub1-w1   <none>           <none>            N
nginx-86dcfdf4c6-pdxb9   member2   1/1     Running   0          4d3h   10.244.1.7     sub1-w1   <none>           <none>            N
In this way, you can use PropagationPolicy to deploy resources collectively to managed clusters.
Testing Multi-cluster Failover
Failover in Karmada is a feature that migrates workloads, such as pods, to surviving clusters when one of the managed clusters goes down. It is easy to understand if you imagine it as a cluster-level extension of the behavior in a regular k8s cluster where pods are restarted on remaining nodes when a worker node fails.
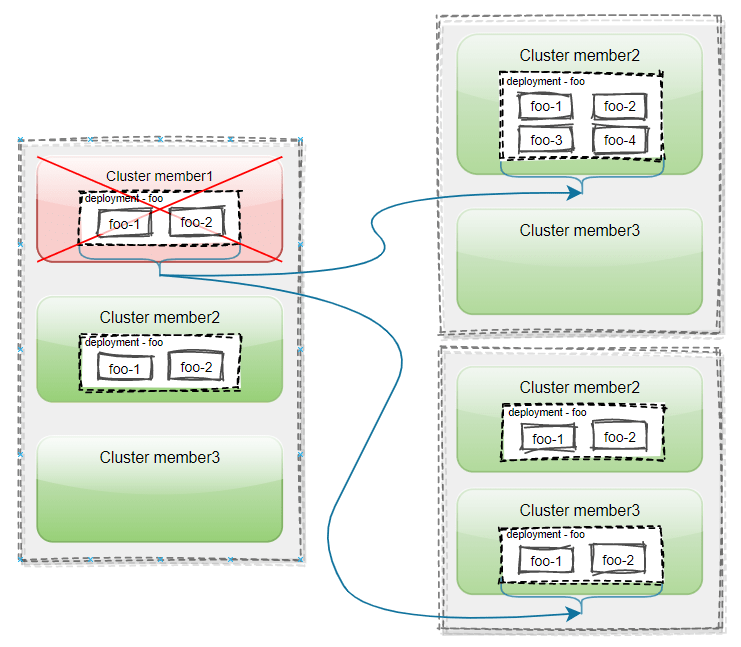
Failover overview diagram. When Cluster member1 goes down, new pods start on member2 or member3 based on the PropagationPolicy settings. Quoted from Failover Overview.
Let's verify this feature as well.
First, we create a manifest to launch 10 nginx pods and a PropagationPolicy to deploy them to the member clusters.
apiVersion: policy.karmada.io/v1alpha1
kind: PropagationPolicy
metadata:
  name: nginx # The default namespace is `default`.
  namespace: default
spec:
  resourceSelectors:
    - apiVersion: apps/v1
      kind: Deployment
      name: nginx # If no namespace is specified, the namespace is inherited from the parent object scope.
      namespace: default
  placement:
    replicaScheduling:
      replicaDivisionPreference: Weighted
      replicaSchedulingType: Divided
      weightPreference:
        staticWeightList:
          - targetCluster:
              clusterNames:
                - member1
            weight: 1
          - targetCluster:
              clusterNames:
                - member2
            weight: 1
The difference from the previous PropagationPolicy is that placement.replicaScheduling is configured to distribute pods equally across each cluster (for details, see Multiple strategies of replica Scheduling). By setting up replicaScheduling as shown above, pods are split and launched based on the weight of the clusters specified in targetCluster. In this case, since the weights for both clusters are set to 1, 5 pods will be launched in each cluster out of the 10 pods total.
When you actually deploy the PropagationPolicy, you can confirm that 5 pods are running in each of the member1 and member2 clusters.
$ k karmada get pod -o wide
NAME                     CLUSTER   READY   STATUS    RESTARTS   AGE   IP             NODE      NOMINATED NODE   READINESS GATES   ADOPTION
nginx-76749dc54c-846qb   member1   1/1     Running   0          35s   10.244.1.98    sub1-w1   <none>           <none>            N
nginx-76749dc54c-b4p9k   member1   1/1     Running   0          35s   10.244.1.99    sub1-w1   <none>           <none>            N
nginx-76749dc54c-hm9lj   member1   1/1     Running   0          35s   10.244.1.100   sub1-w1   <none>           <none>            N
nginx-76749dc54c-mmlpq   member1   1/1     Running   0          35s   10.244.1.97    sub1-w1   <none>           <none>            N
nginx-76749dc54c-tnj4k   member1   1/1     Running   0          35s   10.244.1.101   sub1-w1   <none>           <none>            N
nginx-76749dc54c-76n6w   member2   1/1     Running   0          35s   10.244.1.89    sub2-w1   <none>           <none>            N
nginx-76749dc54c-9d54j   member2   1/1     Running   0          35s   10.244.1.90    sub2-w1   <none>           <none>            N
nginx-76749dc54c-hm96h   member2   1/1     Running   0          35s   10.244.1.92    sub2-w1   <none>           <none>            N
nginx-76749dc54c-jl25p   member2   1/1     Running   0          35s   10.244.1.93    sub2-w1   <none>           <none>            N
nginx-76749dc54c-rqm2n   member2   1/1     Running   0          35s   10.244.1.91    sub2-w1   <none>           <none>            N
Internally, it appears that deployments with divided replicas based on weights are created in each cluster.
$ k get deployments.apps
NAME    READY   UP-TO-DATE   AVAILABLE   AGE
nginx   10/10   10           10          63s

$ k karmada get deployments.apps
NAME    CLUSTER   READY   UP-TO-DATE   AVAILABLE   AGE   ADOPTION
nginx   member1   5/5     5            5           71s   Y
nginx   member2   5/5     5            5           71s   Y
Next, to simulate a situation where the member2 cluster becomes unreachable due to a cluster failure, we will shut down the member2 control-plane node by running sudo shutdown now on it.
After waiting a moment, communication from the Karmada cluster to the member2 cluster will fail, and the status of the member2 cluster will become READY: False.
$ k get cluster
NAME      VERSION   MODE   READY   AGE
member1   v1.29.6   Push   True    3d5h
member2   v1.29.6   Push   False   3d5h
When communication with the member2 cluster is lost, the pods that were running on member2 are started on member1 via Failover to satisfy the deployment's replica count of 10. Simultaneously, a taint is set on the member2 cluster to prevent new pods from being placed there. This can be confirmed in the Events of k describe cluster member2.
$ k describe cluster member2

Events:
  Type    Reason               Age                 From                Message
  ----    ------               ----                ----                -------
  Normal  TaintClusterSucceed  46s (x3 over 3d5h)  cluster-controller  Taint cluster succeed: cluster now has taints([{Key:cluster.karmada.io/not-ready,Effect:NoSchedule}]).
  Normal  TaintClusterSucceed  15s (x2 over 3d4h)  cluster-controller  Taint cluster succeed: cluster now has taints([{Key:cluster.karmada.io/not-ready,Effect:NoSchedule},{Key:cluster.karmada.io/not-ready,Effect:NoExecute}]).
Checking the pods in the member1 cluster, the pod count has reached 10, and those with AGE 3m29s are the pods that were newly started.
$ k karmada get pod -o wide
NAME                     CLUSTER   READY   STATUS    RESTARTS   AGE     IP             NODE      NOMINATED NODE   READINESS GATES   ADOPTION
nginx-76749dc54c-27fxb   member1   1/1     Running   0          3m29s   10.244.1.104   sub1-w1   <none>           <none>            N
nginx-76749dc54c-846qb   member1   1/1     Running   0          12m     10.244.1.98    sub1-w1   <none>           <none>            N
nginx-76749dc54c-8zt7h   member1   1/1     Running   0          3m29s   10.244.1.102   sub1-w1   <none>           <none>            N
nginx-76749dc54c-b4p9k   member1   1/1     Running   0          12m     10.244.1.99    sub1-w1   <none>           <none>            N
nginx-76749dc54c-hm9lj   member1   1/1     Running   0          12m     10.244.1.100   sub1-w1   <none>           <none>            N
nginx-76749dc54c-kj5hs   member1   1/1     Running   0          3m29s   10.244.1.106   sub1-w1   <none>           <none>            N
nginx-76749dc54c-lp9nn   member1   1/1     Running   0          3m29s   10.244.1.105   sub1-w1   <none>           <none>            N
nginx-76749dc54c-mmlpq   member1   1/1     Running   0          12m     10.244.1.97    sub1-w1   <none>           <none>            N
nginx-76749dc54c-tnj4k   member1   1/1     Running   0          12m     10.244.1.101   sub1-w1   <none>           <none>            N
nginx-76749dc54c-zb98z   member1   1/1     Running   0          3m29s   10.244.1.103   sub1-w1   <none>           <none>            N
error: cluster(member2) is inaccessible, please check authorization or network
Note that while the control-plane node including the kube-apiserver is down in the member2 cluster, the pods (containers) running on the worker node remain active. This can be confirmed by checking the containers on the node.
$ sudo nerdctl -n k8s.io ps | grep nginx:latest
19b82ddf0372    docker.io/library/nginx:latest                                                                                      "/docker-entrypoint.…"    18 minutes ago    Up                 k8s://default/nginx-76749dc54c-rqm2n/nginx
614267ce0264    docker.io/library/nginx:latest                                                                                      "/docker-entrypoint.…"    18 minutes ago    Up                 k8s://default/nginx-76749dc54c-hm96h/nginx
8d7684a71103    docker.io/library/nginx:latest                                                                                      "/docker-entrypoint.…"    18 minutes ago    Up                 k8s://default/nginx-76749dc54c-76n6w/nginx
9620b39596e5    docker.io/library/nginx:latest                                                                                      "/docker-entrypoint.…"    18 minutes ago    Up                 k8s://default/nginx-76749dc54c-9d54j/nginx
b7d10132fedc    docker.io/library/nginx:latest                                                                                      "/docker-entrypoint.…"    18 minutes ago    Up                 k8s://default/nginx-76749dc54c-jl25p/nginx
Therefore, the number of pods in the deployment status becomes (the original 10 pods) + (5 pods newly started by Failover) = 15 pods, confirming that it temporarily exceeds the 10 pods defined in the manifest.
$ k get deployments.apps nginx
NAME    READY   UP-TO-DATE   AVAILABLE   AGE
nginx   15/10   15           15          14m

$ k karmada get deployments.apps
NAME    CLUSTER   READY   UP-TO-DATE   AVAILABLE   AGE   ADOPTION
nginx   member1   10/10   10           10          14m   Y
error: cluster(member2) is inaccessible, please check authorization or network
In this way, when an active cluster goes down due to a failure, pods are started in other clusters via Failover.
Now, let's try restarting the node of the member2 cluster that we shut down earlier. Once communication between the Karmada control plane and the target cluster's kube-apiserver is restored, the cluster status returns to READY: True.
$ k get cluster
NAME      VERSION   MODE   READY   AGE
member1   v1.29.6   Push   True    3d5h
member2   v1.29.6   Push   True    3d5h
Even after the failed cluster becomes available again, pod re-placement is not automatically executed. Thus, the number of pods on the member1 cluster remains at 10, and the 5 pods that were running before the failure on the member2 cluster also remain as they are.
NAME                     CLUSTER   READY   STATUS    RESTARTS   AGE   IP             NODE      NOMINATED NODE   READINESS GATES   ADOPTION
nginx-76749dc54c-27fxb   member1   1/1     Running   0          16m   10.244.1.104   sub1-w1   <none>           <none>            N
nginx-76749dc54c-846qb   member1   1/1     Running   0          25m   10.244.1.98    sub1-w1   <none>           <none>            N
nginx-76749dc54c-8zt7h   member1   1/1     Running   0          16m   10.244.1.102   sub1-w1   <none>           <none>            N
nginx-76749dc54c-b4p9k   member1   1/1     Running   0          25m   10.244.1.99    sub1-w1   <none>           <none>            N
nginx-76749dc54c-hm9lj   member1   1/1     Running   0          25m   10.244.1.100   sub1-w1   <none>           <none>            N
nginx-76749dc54c-kj5hs   member1   1/1     Running   0          16m   10.244.1.106   sub1-w1   <none>           <none>            N
nginx-76749dc54c-lp9nn   member1   1/1     Running   0          16m   10.244.1.105   sub1-w1   <none>           <none>            N
nginx-76749dc54c-mmlpq   member1   1/1     Running   0          25m   10.244.1.97    sub1-w1   <none>           <none>            N
nginx-76749dc54c-tnj4k   member1   1/1     Running   0          25m   10.244.1.101   sub1-w1   <none>           <none>            N
nginx-76749dc54c-zb98z   member1   1/1     Running   0          16m   10.244.1.103   sub1-w1   <none>           <none>            N
nginx-76749dc54c-76n6w   member2   1/1     Running   0          25m   10.244.1.89    sub2-w1   <none>           <none>            N
nginx-76749dc54c-9d54j   member2   1/1     Running   0          25m   10.244.1.90    sub2-w1   <none>           <none>            N
nginx-76749dc54c-hm96h   member2   1/1     Running   0          25m   10.244.1.92    sub2-w1   <none>           <none>            N
nginx-76749dc54c-jl25p   member2   1/1     Running   0          25m   10.244.1.93    sub2-w1   <none>           <none>            N
nginx-76749dc54c-rqm2n   member2   1/1     Running   0          25m   10.244.1.91    sub2-w1   <none>           <none>            N
After some time, the pods on the member2 cluster are terminated, returning to the 10 pods defined in the manifest.
NAME                     CLUSTER   READY   STATUS    RESTARTS   AGE   IP             NODE      NOMINATED NODE   READINESS GATES   ADOPTION
nginx-76749dc54c-27fxb   member1   1/1     Running   0          23m   10.244.1.104   sub1-w1   <none>           <none>            N
nginx-76749dc54c-846qb   member1   1/1     Running   0          32m   10.244.1.98    sub1-w1   <none>           <none>            N
nginx-76749dc54c-8zt7h   member1   1/1     Running   0          23m   10.244.1.102   sub1-w1   <none>           <none>            N
nginx-76749dc54c-b4p9k   member1   1/1     Running   0          32m   10.244.1.99    sub1-w1   <none>           <none>            N
nginx-76749dc54c-hm9lj   member1   1/1     Running   0          32m   10.244.1.100   sub1-w1   <none>           <none>            N
nginx-76749dc54c-kj5hs   member1   1/1     Running   0          23m   10.244.1.106   sub1-w1   <none>           <none>            N
nginx-76749dc54c-lp9nn   member1   1/1     Running   0          23m   10.244.1.105   sub1-w1   <none>           <none>            N
nginx-76749dc54c-mmlpq   member1   1/1     Running   0          32m   10.244.1.97    sub1-w1   <none>           <none>            N
nginx-76749dc54c-tnj4k   member1   1/1     Running   0          32m   10.244.1.101   sub1-w1   <none>           <none>            N
nginx-76749dc54c-zb98z   member1   1/1     Running   0          23m   10.244.1.103   sub1-w1   <none>           <none>            N
When the member2 cluster recovers, the taints that were set during the failure are automatically removed, so pods newly created after the recovery will also be placed on member2.
Events:
  Type    Reason               Age                 From                Message
  ----    ------               ----                ----                -------
  Normal  TaintClusterSucceed  24m (x3 over 3d5h)  cluster-controller  Taint cluster succeed: cluster now has taints([{Key:cluster.karmada.io/not-ready,Effect:NoSchedule}]).
  Normal  TaintClusterSucceed  23m (x2 over 3d5h)  cluster-controller  Taint cluster succeed: cluster now has taints([{Key:cluster.karmada.io/not-ready,Effect:NoSchedule},{Key:cluster.karmada.io/not-ready,Effect:NoExecute}]).
  Normal  TaintClusterSucceed  11m (x2 over 3d4h)  cluster-controller  Taint cluster succeed: cluster now has taints([{Key:cluster.karmada.io/not-ready,Effect:NoExecute}]).
  Normal  TaintClusterSucceed  10m (x3 over 3d5h)  cluster-controller  Taint cluster succeed: cluster now does not have taints.
In this way, Karmada automatically adjusts the number of pods after a cluster recovery. However, as seen above, it does not perform re-placement if the distribution of pods across clusters is skewed after the adjustment. In the situation above, the nginx deployment itself on the member2 cluster has been deleted, so commands like pod deletion or kubectl rollout restart will not place pods on the member2 cluster; it is necessary to delete and then recreate the deployment.
$ k karmada get deployments.apps  -C member1
NAME    CLUSTER   READY   UP-TO-DATE   AVAILABLE   AGE   ADOPTION
nginx   member1   10/10   10           10          45m   Y

$ k karmada get deployments.apps  -C member2
No resources found in  namespace.
Other Features
Karmada has many other features, and since there are quite a few, I will briefly introduce some features that I found personally interesting.
Override Policy
Override Policy is a feature that dynamically adds, deletes, or replaces certain properties based on the conditions of the target cluster when deploying resources to multiple clusters. Basically, it can be used for cases where you want to deploy the same deployment but want to change or add labels or annotations for each cluster. The documentation lists the following types of overrides:
| Override Type | Description |
|---|---|
| ImageOverrider | Changes container images |
| CommandOverrider | Changes container commands |
| ArgsOverrider | Changes container arguments |
| LabelsOverrider | Changes resource labels |
| AnnotationsOverrider | Changes resource annotations |
| PlaintextOverrider | Corresponds to a kubectl path and changes any property of the resource |
Deployment with Argo CD
In the previous verification, we manually deployed the target resources and the PropagationPolicy manifests, but in actual production environments, you would likely use a deployment tool like Argo CD to automate the deployment process. The documentation provides instructions on how to deploy with Karmada using Argo CD and Flux.
However, as we saw in the verification, the process basically involves deploying the PropagationPolicy and the target resource manifests separately. Therefore, even when using Argo CD, the flow involves saving these manifests in a GitHub repository and having Argo CD execute the deployment.
Cross-cluster Networking
Since member clusters managed by Karmada are strictly individual clusters, cross-cluster communication requires considering network reachability in a standard network, rather than a flat internal network using a CNI. However, by utilizing OSS that enables cross-cluster networking, you can extend the flat network within a cluster to the cluster level, enabling cross-cluster Service Discovery, AutoScaling, and more.
Note that this functionality is not built directly into Karmada; it requires the use of external components. The documentation describes how to use Submariner, an OSS that provides flat network communication between clusters.
I was also testing cross-cluster Service Discovery using Submariner, but I gave up after struggling to get communication from one cluster to a service in another cluster working (I might try again if I have the chance).
The progress of that verification is documented in the Cross-cluster Networking with Submariner section of the verification notes.
Verification Notes
Notes during verification
Cross-cluster Networking with Submariner
As mentioned in Karmada's cross-cluster networking, using Submariner enables communication between pods and services across clusters. In Submariner, a component called the Broker manages the metadata of the cross-cluster network, and each cluster achieves cross-cluster communication via the Gateway Engine.
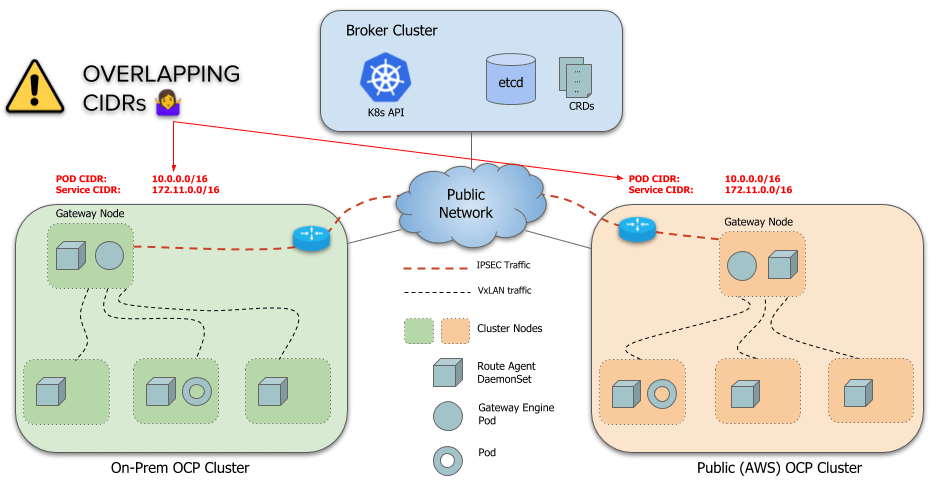
Submariner architecture. Quoted from https://submariner.io/getting-started/architecture/globalnet/
Furthermore, the default setup method has a prerequisite that the ServiceCIDR of each cluster must not overlap; if they do, a mechanism called Globalnet must be used.
However, by default, a limitation of Submariner is that it doesn’t handle overlapping CIDRs (ServiceCIDR and ClusterCIDR) across clusters. Each cluster must use distinct CIDRs that don’t conflict or overlap with any other cluster that is going to be part of the ClusterSet.
Since the three clusters used in this verification all have overlapping Pod CIDRs and ServiceCIDRs, we will build the environment using Globalnet.
Here, we will build the cross-cluster network following the Submariner documentation EXTERNAL NETWORK (EXPERIMENTAL). The documentation prepares two cluster nodes and one non-cluster VM, but the VM is not needed this time, so we will skip it.
Submariner uses the subctl CLI for various operations, so we'll install it.
curl -Ls https://get.submariner.io | bash
export PATH=$PATH:~/.local/bin
echo export PATH=\$PATH:~/.local/bin >> ~/.profile
First, we'll configure the Broker. In Submariner, the Broker is the component that exchanges communication between clusters, and it needs to be built on an API server accessible to all clusters in the cross-cluster network. In this verification, since the Karmada cluster is capable of communicating with each member cluster, we will build the broker on the regular cluster side of the Karmada cluster (not the Karmada control plane) by executing the following command:
export KUBECONFIG=/home/ubuntu/.kube/config
subctl deploy-broker  --globalnet
Next, we will join the other clusters to the Broker, but before that, I'll list the nodes used this time.
| Node Name | Cluster | Node IP Address | Pod CIDR | Role |
|---|---|---|---|---|
| main-m1 | karmada | 10.0.0.40 | 10.244.0.0/16 | control-plane |
| main-w1 | karmada | 10.0.0.41 | - | worker |
| sub1-m1 | member1 | 10.0.0.50 | 10.244.0.0/16 | control-plane |
| sub1-w1 | member1 | 10.0.0.51 | - | worker |
| sub2-m1 | member2 | 10.0.0.30 | 10.244.0.0/16 | control-plane |
| sub2-w1 | member2 | 10.0.0.31 | - | worker |
- Set
CLUSTER_CIDRto10.244.0.0/16as per the documentation. - Set
EXTERNAL_CIDRsuch that it does not overlap with the node IP address ranges of all clusters. Here,10.0.0.96/27is used.
Join the karmada cluster to the broker based on the CIDRs above.
CLUSTER_CIDR=10.244.0.0/16
EXTERNAL_CIDR=10.0.0.96/27
subctl join broker-info.subm --clusterid karmada --natt=false --clustercidr=${CLUSTER_CIDR},${EXTERNAL_CIDR}
Next, join the member1 and member2 clusters to the broker.
subctl join --kubeconfig /home/ubuntu/.kube/sub1.config  broker-info.subm --clusterid member1 --natt=false
subctl join --kubeconfig /home/ubuntu/.kube/sub2.config  broker-info.subm --clusterid member2 --natt=false
You can check the current connection status of the clusters with subctl show all. It is OK if connections and gateways are displayed and no errors appear.
$ subctl show all

Cluster "main_k8s"
 ✓ Detecting broker(s)
NAMESPACE               NAME                COMPONENTS                        GLOBALNET   GLOBALNET CIDR   DEFAULT GLOBALNET SIZE   DEFAULT DOMAINS
submariner-k8s-broker   submariner-broker   service-discovery, connectivity   yes         242.0.0.0/8      65536

 ✓ Showing Connections
GATEWAY   CLUSTER   REMOTE IP   NAT   CABLE DRIVER   SUBNETS        STATUS      RTT avg.
sub1-w1   member1   10.0.0.51   no    libreswan      242.1.0.0/16   connected   852.419µs
sub2-w1   member2   10.0.0.31   no    libreswan      242.2.0.0/16   connected   835.722µs

 ✓ Showing Endpoints
CLUSTER   ENDPOINT IP   PUBLIC IP        CABLE DRIVER   TYPE
karmada   10.0.0.41     118.158.73.193   libreswan      local
member1   10.0.0.51     118.158.73.193   libreswan      remote
member2   10.0.0.31     118.158.73.193   libreswan      remote

 ✓ Showing Gateways
NODE      HA STATUS   SUMMARY
main-w1   active      All connections (2) are established

 ✓ Showing Network details
    Discovered network details via Submariner:
        Network plugin:  generic
        Service CIDRs:   [10.96.0.0/12]
        Cluster CIDRs:   [10.244.0.0/16,10.0.0.96/27]
        Global CIDR:     242.0.0.0/16

 ✓ Showing versions
COMPONENT                       REPOSITORY           CONFIGURED   RUNNING                     ARCH
submariner-gateway              quay.io/submariner   0.17.1       release-0.17-fdfcc8797bc2   amd64
submariner-routeagent           quay.io/submariner   0.17.1       release-0.17-fdfcc8797bc2   amd64
submariner-globalnet            quay.io/submariner   0.17.1       release-0.17-fdfcc8797bc2   amd64
submariner-metrics-proxy        quay.io/submariner   0.17.1       release-0.17-1e49b8404147   amd64
submariner-operator             quay.io/submariner   0.17.1       release-0.17-0133a99b08a6   amd64
submariner-lighthouse-agent     quay.io/submariner   0.17.1       release-0.17-b9c6b562f556   amd64
submariner-lighthouse-coredns   quay.io/submariner   0.17.1       release-0.17-b9c6b562f556   amd64
Upon completion of the setup, the following pods are created in the submariner-operator namespace:
$ k get pod -n submariner-operator
NAME                                             READY   STATUS    RESTARTS   AGE
submariner-gateway-s9hcc                         1/1     Running   0          3d3h
submariner-globalnet-gklkd                       1/1     Running   0          3d3h
submariner-lighthouse-agent-754bfcf58c-klf5q     1/1     Running   0          3d3h
submariner-lighthouse-coredns-7fb549f74d-jq2zx   1/1     Running   0          3d3h
submariner-lighthouse-coredns-7fb549f74d-vrgf5   1/1     Running   0          3d3h
submariner-metrics-proxy-dmg4w                   2/2     Running   0          3d3h
submariner-operator-ffc859cfd-w9sfw              1/1     Running   0          3d3h
submariner-routeagent-7jlwn                      1/1     Running   0          3d3h
submariner-routeagent-h8dlk                      1/1     Running   0          3d3h
Now that the cross-cluster network is configured, we will verify the operation according to Karmada's Multi-cluster Service Discovery.
First, create the serviceexports and serviceimport CRDs on the member clusters. Create a ClusterPropagationPolicy manifest as shown below.
# propagate ServiceExport CRD
apiVersion: policy.karmada.io/v1alpha1
kind: ClusterPropagationPolicy
metadata:
  name: serviceexport-policy
spec:
  resourceSelectors:
    - apiVersion: apiextensions.k8s.io/v1
      kind: CustomResourceDefinition
      name: serviceexports.multicluster.x-k8s.io
  placement:
    clusterAffinity:
      clusterNames:
        - member1
        - member2
---
# propagate ServiceImport CRD
apiVersion: policy.karmada.io/v1alpha1
kind: ClusterPropagationPolicy
metadata:
  name: serviceimport-policy
spec:
  resourceSelectors:
    - apiVersion: apiextensions.k8s.io/v1
      kind: CustomResourceDefinition
      name: serviceimports.multicluster.x-k8s.io
  placement:
    clusterAffinity:
      clusterNames:
        - member1
        - member2
By deploying this on Karmada, the CRDs will be created on both member clusters at once.
export KUBECONFIG=/home/ubuntu/.kube/karmada.config
k apply -f svc-crd.yml
Next, create and deploy the following manifests as described in the documentation.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: serve
spec:
  replicas: 1
  selector:
    matchLabels:
      app: serve
  template:
    metadata:
      labels:
        app: serve
    spec:
      containers:
      - name: serve
        image: jeremyot/serve:0a40de8
        args:
        - "--message='hello from cluster member1 (Node: {{env \"NODE_NAME\"}} Pod: {{env \"POD_NAME\"}} Address: {{addr}})'"
        env:
          - name: NODE_NAME
            valueFrom:
              fieldRef:
                fieldPath: spec.nodeName
          - name: POD_NAME
            valueFrom:
              fieldRef:
                fieldPath: metadata.name
---
apiVersion: v1
kind: Service
metadata:
  name: serve
spec:
  ports:
  - port: 80
    targetPort: 8080
  selector:
    app: serve
---
apiVersion: policy.karmada.io/v1alpha1
kind: PropagationPolicy
metadata:
  name: mcs-workload
spec:
  resourceSelectors:
    - apiVersion: apps/v1
      kind: Deployment
      name: serve
    - apiVersion: v1
      kind: Service
      name: serve
  placement:
    clusterAffinity:
      clusterNames:
        - member1
apiVersion: multicluster.x-k8s.io/v1alpha1
kind: ServiceExport
metadata:
  name: serve
---
apiVersion: policy.karmada.io/v1alpha1
kind: PropagationPolicy
metadata:
  name: serve-export-policy
spec:
  resourceSelectors:
    - apiVersion: multicluster.x-k8s.io/v1alpha1
      kind: ServiceExport
      name: serve
  placement:
    clusterAffinity:
      clusterNames:
        - member1
apiVersion: multicluster.x-k8s.io/v1alpha1
kind: ServiceImport
metadata:
  name: serve
spec:
  type: ClusterSetIP
  ports:
  - port: 80
    protocol: TCP
---
apiVersion: policy.karmada.io/v1alpha1
kind: PropagationPolicy
metadata:
  name: serve-import-policy
spec:
  resourceSelectors:
    - apiVersion: multicluster.x-k8s.io/v1alpha1
      kind: ServiceImport
      name: serve
  placement:
    clusterAffinity:
      clusterNames:
        - member2
Deploying the above will result in the following behavior:
-
servepods and services are created on themember1cluster. - A
serveservice accessible across clusters is created via theServiceExportCRD. - A service for accessing
serveis created on themember2cluster via theServiceImportCRD.
Due to the nature of Submariner, exposing a specific service with the subctl export command or creating a ServiceExport CRD results in the creation of a service that is globally accessible across clusters. This can be verified as a globalingressips resource.
$ k karmada get globalingressips.submariner.io -A
NAMESPACE   NAME            CLUSTER   IP              ADOPTION
default     serve           member1   242.1.255.253   N
default     derived-serve   member2   242.2.255.253   N
The serve entry above corresponds to the global endpoint of the service created on the member1 cluster, and the IP address is used to connect to that endpoint. Additionally, checking the services on the member1 cluster reveals that a submariner-.. service has been created, with the IP address confirmed above set as the EXTERNAL-IP.
$ k get svc
NAME                                          TYPE        CLUSTER-IP       EXTERNAL-IP     PORT(S)   AGE
kubernetes                                    ClusterIP   10.96.0.1        <none>          443/TCP   26h
serve                                         ClusterIP   10.102.199.123   <none>          80/TCP    98s
submariner-etcfrt5unwnek3jrjr4joya6kfly4q6b   ClusterIP   10.99.110.190    242.1.255.253   80/TCP    98s
By accessing this IP address, the serve pod on the member1 cluster can be reached not only from the nodes of the member1 cluster but also from the nodes of the karmada and member2 clusters.
$ curl 242.1.255.253
'hello from cluster member1 (Node: sub1-w1 Pod: serve-8765f9f98-7n4zm Address: 10.244.1.91)'
Furthermore, the created global endpoint can be resolved within the pod network using [service_name].[namespace].svc.clusterset.local. This can be verified by launching a temporary pod in the member2 cluster and running nslookup or dig from within the pod.
root@nginx-76749dc54c-czzsk:/# nslookup  serve.default.svc.clusterset.local
Server:         10.96.0.10
Address:        10.96.0.10#53

Name:   serve.default.svc.clusterset.local
Address: 242.1.255.253

# dig
root@nginx-76749dc54c-czzsk:/# dig  serve.default.svc.clusterset.local

; <<>> DiG 9.18.24-1-Debian <<>> serve.default.svc.clusterset.local
;; global options: +cmd
;; Got answer:
;; WARNING: .local is reserved for Multicast DNS
;; You are currently testing what happens when an mDNS query is leaked to DNS
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 27186
;; flags: qr aa rd; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available

;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
; COOKIE: f738fcff83c7111c (echoed)
;; QUESTION SECTION:
;serve.default.svc.clusterset.local. IN A

;; ANSWER SECTION:
serve.default.svc.clusterset.local. 5 IN A      242.1.255.253

;; Query time: 0 msec
;; SERVER: 10.96.0.10#53(10.96.0.10) (UDP)
;; WHEN: Sat Jun 22 10:10:13 UTC 2024
;; MSG SIZE  rcvd: 125
In this way, Submariner assigns a globally valid IP address to a k8s service across clusters.
The relationship between the services created above is illustrated in the diagram below. When a service is exposed via service export, a corresponding submariner-... service is created and assigned an EXTERNAL-IP (globalingressips). Through this, communication between clusters belonging to the Submariner network is realized.
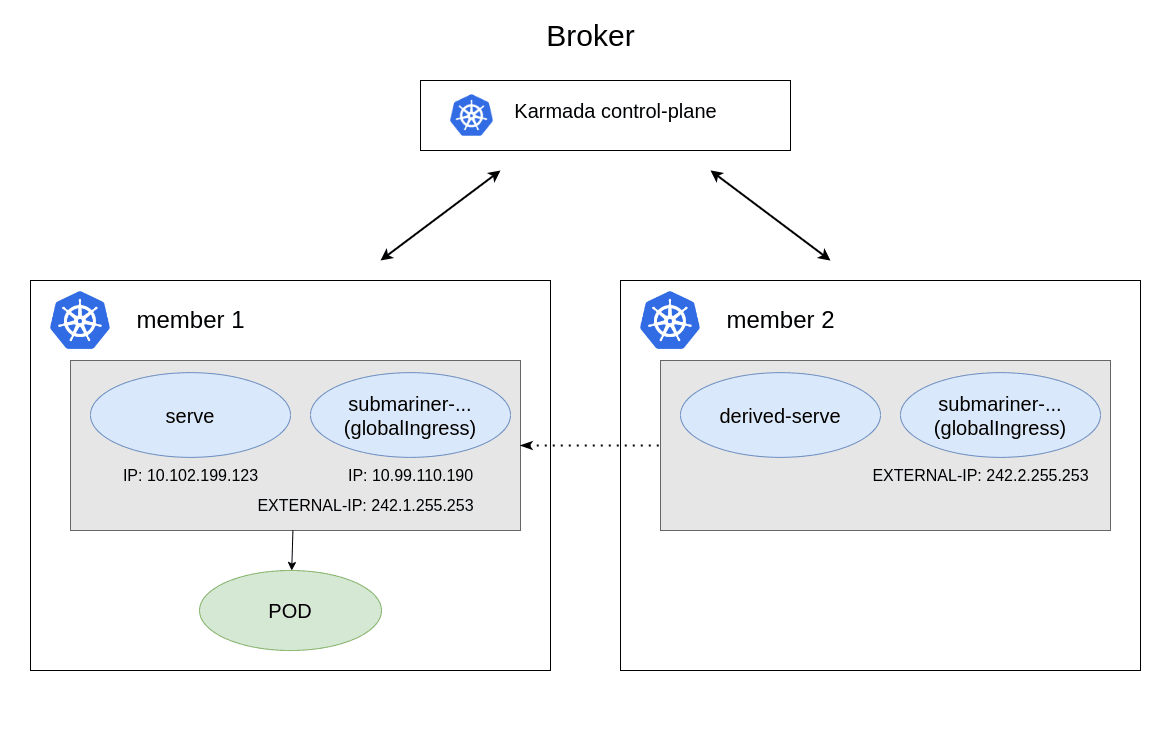
Conceptual diagram
In Step 3: Access the service from member2 cluster, it is mentioned that as part of Karmada's Service Discovery feature, routing to the member1 cluster's pod should be possible by accessing derived-serve. However, when I tried it myself, the service and pods were not correctly linked, and it did not work. It is possible that my configuration was incorrect.
Conclusion
We have verified the behavior of multi-cluster resource deployment and Failover using the k8s multi-cluster management OSS, Karmada. While there are many unique concepts and components in Karmada, leading to a somewhat high learning curve, and the management costs and operational methods for full-scale multi-cluster management can be complex, I felt that it is definitely an option if you want to achieve multi-cluster management using open-source software. Nevertheless, since it is a CNCF incubating project, further development and functional expansions are expected in response to the growing demand for multi-cloud and multi-cluster management in recent years.
Discussion