iTranslated by AI
Displaying Electronic Official Documents (XML+XSL) in Chrome





What are Electronic Official Documents?
Electronic official documents refer to official documents created, stored, and managed in electronic format. This includes official documents issued by government agencies and corporations. Electronic official documents may have the same legal validity as paper documents, and their reliability and security are ensured through digital signatures and encryption technologies.
Some of these electronic official documents are created in XML+XSL format. XML is a markup language for describing data in a structured way, and XSL is a stylesheet language for transforming XML documents into other formats. While electronic official documents in XML+XSL format can be displayed in a web browser, there are several restrictions on how they are displayed.
How to Display Electronic Official Documents
To display an electronic official document in a web browser, the XML+XSL format file must be converted to HTML format. This conversion is performed using a technology called XSLT (XSL Transformations). XSLT is a stylesheet language for converting XML documents into other formats, and it allows for converting XML documents into HTML format using XSL files.
The following information is provided regarding how to display electronic official documents in a web browser:
- Q. Please tell me how to open an official document in XML file format.
https://shinsei.e-gov.go.jp/contents/help/faq/document.html
The instructions suggest using IE11 compatibility mode in Microsoft Edge or disabling local file restrictions in Safari.
To be blunt, it's nothing short of terrible. There is no proper way to display them. They should really be distributed in a more versatile format.
How to Display in Chrome
In Chrome, even if you drag and drop an XML+XSL file, it won't be displayed. However, since XSL is supported by web standards, it can be converted to HTML using XSLTProcessor. But because it requires API calls, you need to write a script for the conversion.
So, I created a conversion script. Since electronic official documents are distributed in ZIP format, I made it possible to drag and drop the ZIP files directly. While browsers support deflate—the compression algorithm used in ZIPs—they do not support the ZIP file format itself. Therefore, you have to write the logic for extracting compressed data from the ZIP file yourself. Furthermore, the ZIP format used for electronic official documents is quite tricky, as it uses a legacy sequential format. What this means is that the header containing the compressed data size is located after the data body, making it a very difficult format to handle. Since the data size is unknown, you cannot read the data without first finding the subsequent header. It is quite rare to encounter a system that creates ZIP files in such a format nowadays.
Here is the code to extract the ZIP file and convert XML+XSL to HTML.
<!DOCTYPE html>
<html>
  <head>
    <title>XSL Viewer</title>
    <meta charset="utf-8" />
    <meta name="viewport" content="width=device-width, initial-scale=1" />
    <style>
      html,
      body {
        min-height: 100%;
        min-width: 100%;
        margin: 0;
        padding: 0;
      }
    </style>
    <script>
      /**
       * @param {arrayBuffer} ArrayBuffer
       * @returns {Promise<File[]>}
       */
      const decompressZip = async (arrayBuffer) => {
        async function decompressData(compressedData) {
          const reader = new Blob([compressedData])
            .stream()
            .pipeThrough(new DecompressionStream("deflate-raw"))
            .getReader();
          const chunks = [];
          let result = await reader.read();
          while (!result.done) {
            chunks.push(result.value);
            result = await reader.read();
          }
          return new Blob(chunks);
        }

        const dataView = new DataView(arrayBuffer);
        let offset = 0;
        const files = [];

        while (offset < dataView.byteLength) {
          const signature = dataView.getUint32(offset, true);
          if (signature !== 0x04034b50) break;
          const generalPurposeFlag = dataView.getUint16(offset + 6, true);
          const fileNameLength = dataView.getUint16(offset + 26, true);
          const extraFieldLength = dataView.getUint16(offset + 28, true);
          let compressedSize = dataView.getUint32(offset + 18, true);
          const pathName = new TextDecoder().decode(
            arrayBuffer.slice(offset + 30, offset + 30 + fileNameLength)
          );
          offset += fileNameLength + extraFieldLength + 30;
          const dataOffset = offset;
          const isDataDescriptor = (generalPurposeFlag & 0x0008) !== 0;

          if (isDataDescriptor) {
            while (offset < dataView.byteLength) {
              const potentialSignature = dataView.getUint32(offset, true);
              if (potentialSignature === 0x08074b50) {
                compressedSize = dataView.getUint32(offset + 8, true);
                offset += 16;
                break;
              }
              offset++;
            }
          } else {
            offset += compressedSize;
          }

          if (pathName[pathName.length - 1] !== "/") {
            const decompressedData = await decompressData(
              arrayBuffer.slice(dataOffset, dataOffset + compressedSize)
            );
            const fileName = pathName.replace(/.*\//, "");
            files.push(new File([decompressedData], fileName));
          }
        }
        return files;
      };
      /**
       * @param {File[]} sourceFiles
       * @returns {Promise<[string, string][]>}
       * */
      const convertXsl = async (sourceFiles) => {
        const unCompressPromises = sourceFiles.map(async (file) => {
          if (file.type === "application/x-zip-compressed") {
            return file.arrayBuffer().then(decompressZip);
          }
          return file;
        });
        const unCompressFiles = Promise.all(unCompressPromises).then(
          (files) => {
            return files.flat();
          }
        );
        const documentFiles = unCompressFiles.then(async (files) => {
          return Promise.all(
            files
              .filter((file) => file.name.match(/\.xml$|\.xsl$/))
              .map(async (file) => {
                const parser = new DOMParser();
                const xml = parser.parseFromString(
                  await file.text(),
                  "application/xml"
                );
                return [file.name, xml];
              })
          );
        });
        return documentFiles.then((files) => {
          const fileMap = Object.fromEntries(files);
          const xmlDocs = files.filter(([name]) => name.endsWith(".xml"));
          const documents = xmlDocs.map(([name, xmlDoc]) => {
            const xsltProcessor = new XSLTProcessor();
            const styleNodes = Array.from(xmlDoc.childNodes).filter(
              (node) =>
                node.nodeType === Node.PROCESSING_INSTRUCTION_NODE &&
                node.target === "xml-stylesheet"
            );
            styleNodes.forEach((styleNode) => {
              const href = styleNode.data.match(/href="([^"]+)"/)[1];
              const xslDoc = fileMap[href];
              if (xslDoc) xsltProcessor.importStylesheet(xslDoc);
            });
            const resultDoc = xsltProcessor.transformToDocument(xmlDoc);
            const serializer = new XMLSerializer();
            const resultString = serializer.serializeToString(resultDoc);
            return [name, resultString];
          });
          return documents;
        });
      };
      const handleDrop = (e) => {
        e.preventDefault();
        convertXsl(Array.from(e.dataTransfer.files)).then((docs) => {
          const body = document.body;
          body.innerHTML = "";
          const nodes = docs.map(([name, doc]) => {
            const contents = document.createElement("div");
            contents.innerHTML = doc;
            const div = document.createElement("div");
            div.style.padding = "16px";
            const header = document.createElement("h1");
            header.innerText = name;
            const hr = document.createElement("hr");
            div.append(header, contents, hr);
            return div;
          });
          body.append(...nodes);
        });
      };
    </script>
  </head>
  <body ondragover="event.preventDefault()" ondrop="handleDrop(event)">
    <div
      style="
        height: 100vh;
        display: flex;
        justify-content: center;
        align-items: center;
      "
    >
      <span
        style="
          padding: 16px;
          font-size: 2em;
          border: 2px dashed black;
          border-radius: 16px;
        "
      >
        Drop files or zip-file here
      </span>
    </div>
  </body>
</html>
You can try it out at the following address:
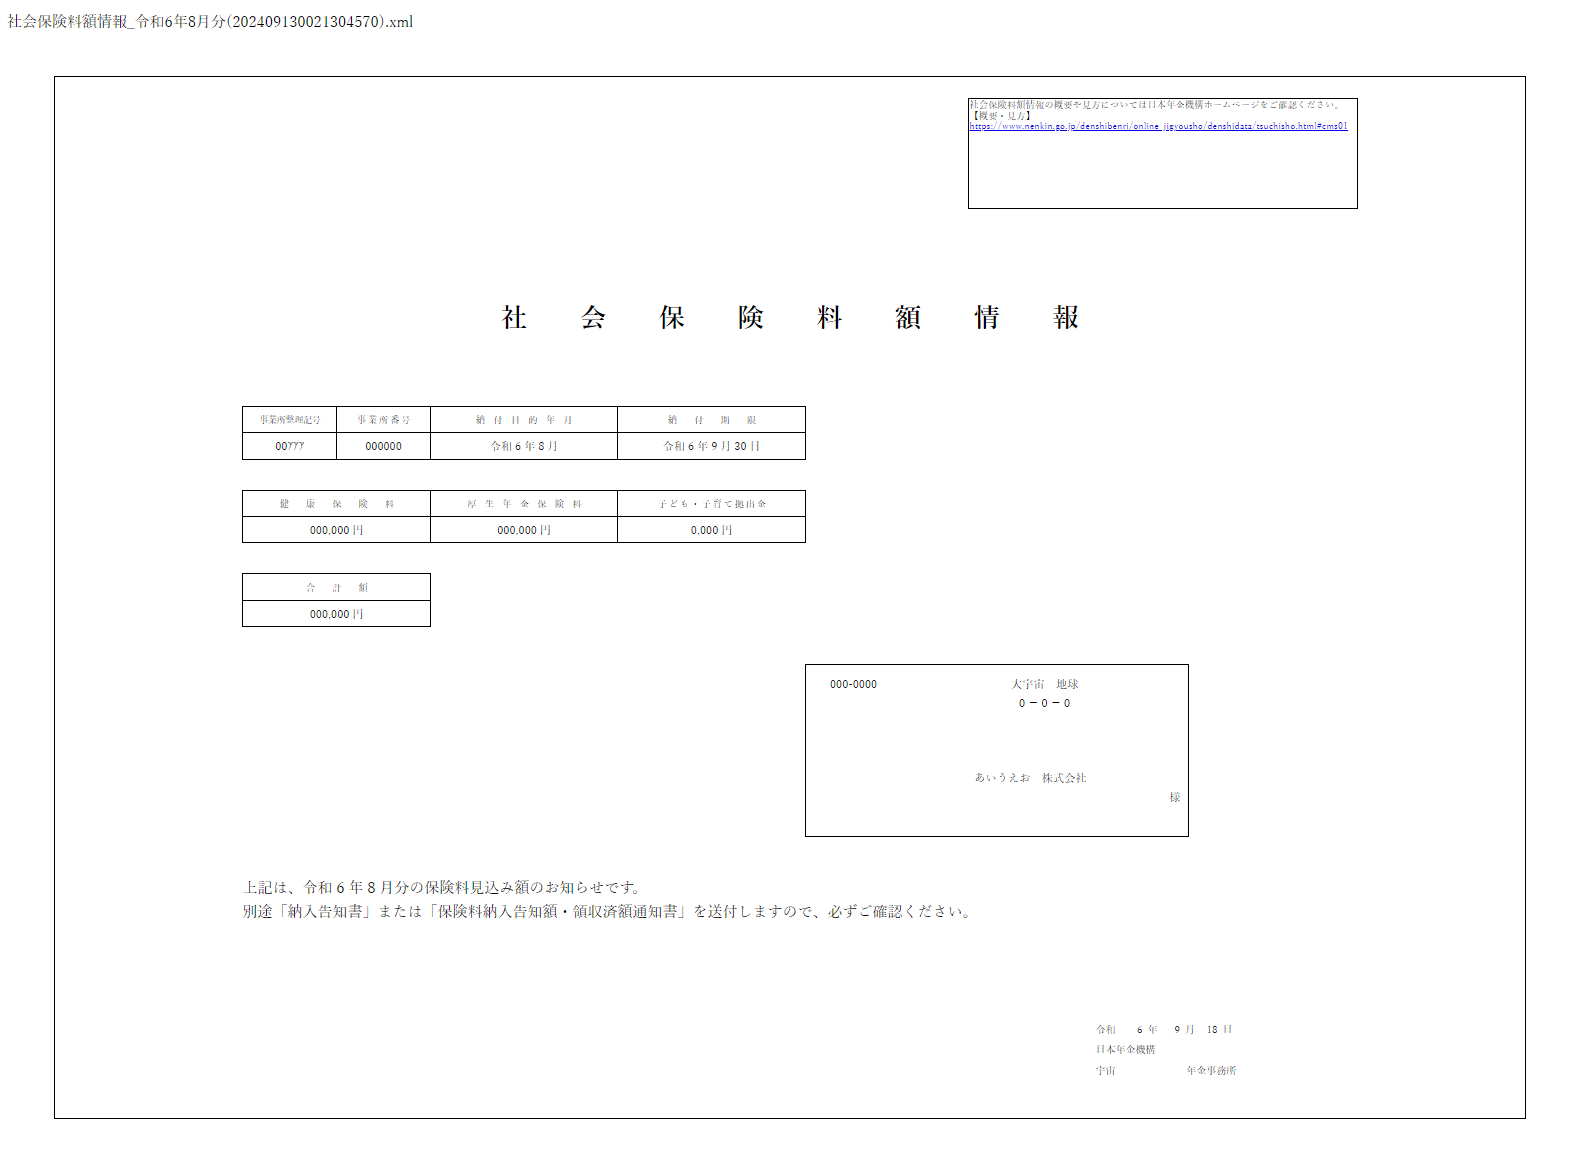
Here is an example of displaying a social insurance premium notification:
Summary
I have introduced a method to display electronic official documents in XML+XSL format in Chrome. In this instance, I implemented the solution using only standard APIs without any external libraries. Since the logic itself is not that complex, it was manageable enough to fit entirely within a single HTML file.
Discussion
めちゃくちゃ便利です!ありがとうございます!!!
素晴らしいです。助かりました
昨年から毎月使っています。ありがとうございます。
ネットで探さないと開けない公文書をなぜ作成するのか?
不思議でなりません。
素晴らしい。ありがとうございます。
解凍、数クリックしてようやく見ることが出来るゴミシステム。雇用保険の様にせめてPDFにしてほしい。
いまだに使い続ける意味がよくわかりません。
研修会、説明会のアンケートでは、従来の紙イメージのレイアウトと合わせて毎回クレームを書いています。
定期調査の時も毎回言っていますが、調査官は初めて聞いたという回答で、意見があったと上にあげると言われますが、全くダメですね。
数十万?払って市販ソフトを買えってことなんでしょうかね。(それが使いやすいのかは知りませんが。)
とにかくUI、UXが最悪ですね。
おかげさまで少しUXが改善されました。
ありがとうございます
大変助かりました