iTranslated by AI
Running Qwen2-VL Locally





Introduction
Who is this article for?
- Those interested in Generative AI, especially VLMs (Vision Language Models)
- Those interested in Qwen2-VL
- Those who want to run Qwen2-VL in a local environment (Windows, Ubuntu, Mac)
1. Mac Studio (M2 Ultra 128GB)
2. Windows 10 (System Memory 96GB + RTX 3060 12GB)
★Update: Monday, 2024-11-18
This article focuses on running sample programs, so it might be less practical for everyday use.
If you want to use it as a Web UI or API, I recommend the following methods instead of the ones described in this article.
- Using web_demo_mm.py by following the README in the official repository
- Setting up a vllm server and using it with Open WebUI, etc. (NVIDIA environments only)
Content
In this article, I will try out Qwen2-VL, the latest VLM announced by Alibaba Cloud, in a local environment.
I will mainly cover the following points:
- How to run Qwen2-VL locally
- Windows, Ubuntu, Mac
- Tips for running in a Mac environment
- Usage examples of Qwen2-VL (Image + Text)
- Inference speed (Actual measurements)
However, the 2B model may not run or might be quite slow unless you have at least 12GB of VRAM (it might barely work with 8GB). The 7B model might not be enough even with 24GB.
Installation Procedures
In this article, I will document the steps to run Qwen2-VL-2B-Instruct in a local environment. The steps are exactly the same for the 7B version, except for the model itself. While the basic instructions are on the Hugging Face page, I have also included some steps that were omitted there.
I will try to write in a way that is compatible with Windows, Ubuntu, and Mac (Apple Silicon) environments as much as possible, but please adjust the CUDA-related parts according to your environment as needed.
Downloading the Model and Required Modules
- From model download to Python virtual environment creation
$ git lfs install
$ git clone https://huggingface.co/Qwen/Qwen2-VL-2B-Instruct
$ cd Qwen2-VL-2B-Instruct
$ python3 -m venv venv
*If git lfs install is not available, please ensure git-lfs is installed beforehand.
- Activating the virtual environment
$ source venv/bin/activate
$ .\\venv\\Scripts\\activate
- Installing required modules
$ pip install git+https://github.com/huggingface/transformers
$ pip install qwen-vl-utils
$ pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124
$ pip install accelerate>=0.26.0
$ pip install git+https://github.com/huggingface/transformers
$ pip install qwen-vl-utils
$ pip install torch torchvision
$ pip install accelerate
Execution Python Script
Create an execution script main.py inside the Qwen2-VL-2B-Instruct directory. The code is basically copy-pasted from Hugging Face, but I have modified it slightly because I didn't want the model to be downloaded to an arbitrary location.
Also, the script below reads an input image from Qwen2-VL-2B-Instruct/input/test_01.png and uses the prompt "Please describe this image in detail." Please prepare your own image and store it in Qwen2-VL-2B-Instruct/input/. Additionally, the max token count is set to 1024, but you can change this as you like.
Execution Python script for Windows/Ubuntu (CUDA environment)
from transformers import Qwen2VLForConditionalGeneration, AutoTokenizer, AutoProcessor
from qwen_vl_utils import process_vision_info

# default: Load the model on the available device(s)
model = Qwen2VLForConditionalGeneration.from_pretrained(
    "../Qwen2-VL-2B-Instruct", torch_dtype="auto", device_map="auto"
)

# We recommend enabling flash_attention_2 for better acceleration and memory saving, especially in multi-image and video scenarios.
# model = Qwen2VLForConditionalGeneration.from_pretrained(
#     "Qwen/Qwen2-VL-2B-Instruct",
#     torch_dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )

# default processer
processor = AutoProcessor.from_pretrained("../Qwen2-VL-2B-Instruct")

# The default range for the number of visual tokens per image in the model is 4-16384. You can set min_pixels and max_pixels according to your needs, such as a token count range of 256-1280, to balance speed and memory usage.
# min_pixels = 256*28*28
# max_pixels = 1280*28*28
# processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-2B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": "input/test_01.png",
            },
            {"type": "text", "text": "Please describe this image in detail."},
        ],
    }
]

# Preparation for inference
text = processor.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True
)
image_inputs, video_inputs = process_vision_info(messages)
inputs = processor(
    text=[text],
    images=image_inputs,
    videos=video_inputs,
    padding=True,
    return_tensors="pt",
)
inputs = inputs.to("cuda")

# Inference: Generation of the output
generated_ids = model.generate(**inputs, max_new_tokens=1024)
generated_ids_trimmed = [
    out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
- For Mac (Apple Silicon environment)
For the Mac script, just copy and paste the above and modify the following single line. This change allows Qwen2-VL to run on Apple Silicon.
-   inputs = inputs.to("cuda")
+   inputs = inputs.to("mps")
With this, the preparations for running Qwen2-VL-2B-Instruct should be complete.
Execution Examples
The following are the responses from the 2B, 7B, and 72B models when three different images were input, all using the prompt "Please describe this image in detail." Note that for the 2B and 7B models, only the output from the RTX 3060 is provided.
① Image Description
- Input image: Photo taken at Kakegawa Bird and Flower Park
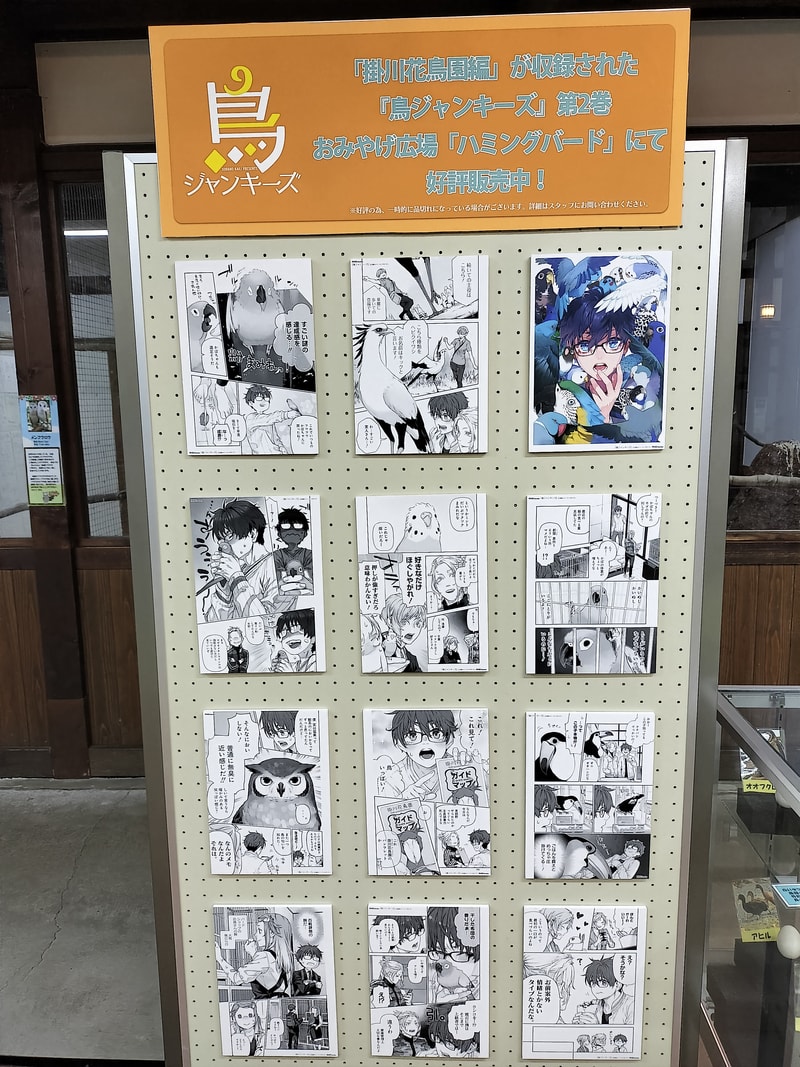
2B Output
This image is a display board for the "Tori Junkies" manga. There are 12 manga pages displayed on the board. Each page depicts different characters and scenes, expressed in different styles and color tones for each page.
The "Tori Junkies" logo is displayed in the upper-left corner, and the title "Tori Junkies Volume 2" is displayed in the upper-right corner. At the bottom, information saying "Now on sale!" is shown.
While the titles and character names for each page are unknown, the overall theme depicts the relationship between birds and humans. Particularly in the bottom-right page, a scene with a bird and a human together is shown.
7B Output
This image shows a place where posters and flyers for Japanese manga and anime are displayed. The posters and flyers depict various characters and scenes.
At the top, there is a sign with black text on a yellow background. The sign contains the title "Tori Junkies" and information about Volume 2 of the work.
At the bottom, 12 posters are lined up. These posters depict different characters and scenes, and some include illustrations of birds and animals. The poster designs include both monochrome and color versions, each with a unique style.
Overall, it indicates that this is a place where anime and manga fans can enjoy themselves.
72B Output
This image shows a manga exhibition panel. At the top of the panel, there is a sign with a yellow background containing Japanese text. The text announces that the "Kakegawa Kahoen Edition," which is included in the second volume of "Tori Junkies," is now on sale at the souvenir shop "Hummingbird."
Multiple manga pages are displayed on the panel. Each page depicts character dialogue and scenes, with some pages including color illustrations. The style of the manga is a mix of both monochrome and color.
The content of the displayed manga is themed around birds and animals, depicting conversations and actions of the characters. In the upper right of the panel, a scene where a character with purple hair is hugging a bird is drawn in color.
Overall, this panel is for promoting the "Tori Junkies" manga and displays various scenes to convey the appeal of the work to readers.
② Loading a Workflow
- Input image: Flow of LLM Werewolf Game
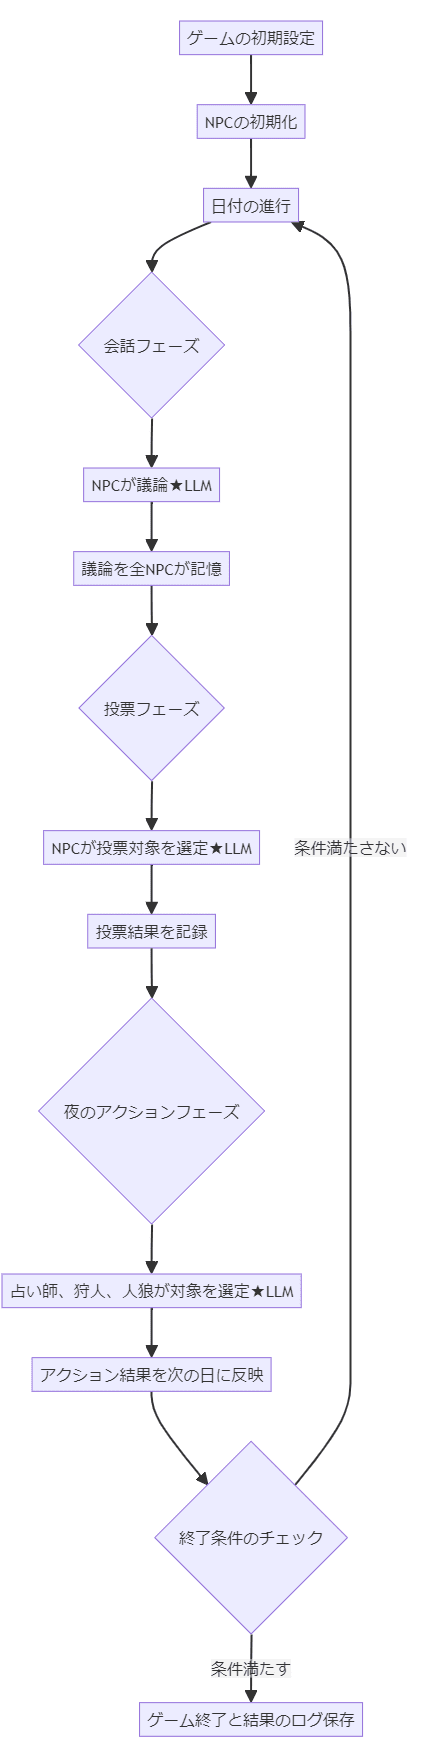
2B Output
This image shows the process from the initial game settings to the initialization of NPCs. The details are as follows:
- Initial Game Settings: Basic game settings are performed.
- NPC Initialization: Initial settings for NPCs (Non-Player Characters) are performed.
- Date Progression: The game progress advances.
- Conversation Phase: Conversations between NPCs and users take place.
- NPCs Discuss: NPCs may engage in discussions.
- All NPCs Remember the Discussion: The discussion is stored in the memory of all NPCs.
- Voting Phase: NPCs may conduct a vote.
- NPCs Select Voting Targets: NPCs select the targets for their votes.
- Record Voting Results: Voting results are recorded.
- Night Action Phase: NPCs may perform actions during the night.
- Seer, Hunter, and Werewolf Select Targets: The Seer, Hunter, and Werewolf select their targets.
- Reflect Action Results in the Next Day: The results of actions are reflected in the following day.
- Check Termination Conditions: If termination conditions are met, the game ends, and the result log is saved.
This process shows the basic flow of the game, with the necessary processing performed at each step.
7B Output
This image shows a flowchart of the game. Below is a detailed explanation of each step.
-
Initial Game Settings:
- All settings required at the start of the game are performed.
-
NPC Initialization:
- NPCs (Non-Player Characters) are initialized.
-
Date Progression:
- The date advances, and the game progression moves forward.
-
Conversation Phase:
- Conversations between NPCs and players begin.
-
NPCs Discuss ★LLM:
- NPCs discuss and record the results.
-
All NPCs Remember the Discussion:
- All NPCs memorize the results of the discussion.
-
Voting Phase:
- This is the phase where players conduct voting.
-
NPCs Select Voting Targets ★LLM:
- NPCs select voting targets and record the results.
-
Record Voting Results:
- Voting results are recorded.
-
Night Action Phase:
- The night action phase begins.
-
Seer, Hunter, and Werewolf Select Targets ★LLM:
- The Seer, Hunter, and Werewolf select their targets.
-
Reflect Action Results in the Next Day:
- Action results are reflected in the following day.
-
Check Termination Conditions:
- Termination conditions are checked to determine if they are met.
-
Conditions Met:
- If conditions are met, the game ends, and the results are saved in a log.
-
Game End and Result Log Saving:
- The game ends, and the results are saved in a log.
This flowchart illustrates the progression of the game and the flow of each phase.
72B Output
This image shows a flowchart of the game. Below is a detailed explanation of each step.
- Initial Game Settings: Perform settings required before the game starts.
- NPC Initialization: Perform initial settings for NPCs (Non-Player Characters).
- Date Progression: The date within the game advances.
- Conversation Phase: A phase where NPCs engage in discussion.
- NPCs Discuss: NPCs conduct a discussion.
- All NPCs Remember the Discussion: All NPCs memorize the discussion.
- Voting Phase: A phase where NPCs conduct voting.
- NPCs Select Voting Targets: NPCs select the targets for their votes.
- Record Voting Results: Record the voting results.
- Night Action Phase: A phase for performing night actions.
- Seer, Hunter, and Werewolf Select Targets: The Seer, Hunter, and Werewolf select their targets.
- Reflect Action Results in the Next Day: Results of the actions are reflected in the following day.
- Check Termination Conditions: Check the conditions for ending the game.
- Conditions not met: If conditions are not met, the date advances and the process starts again from the conversation phase.
- Conditions met: If conditions are met, the game ends and the result log is saved.
This flowchart shows the game progression and details of each phase, illustrating how NPC actions, voting, and action results affect the game.
③ OCR of Documents Containing Mathematical Formulas
- Input image
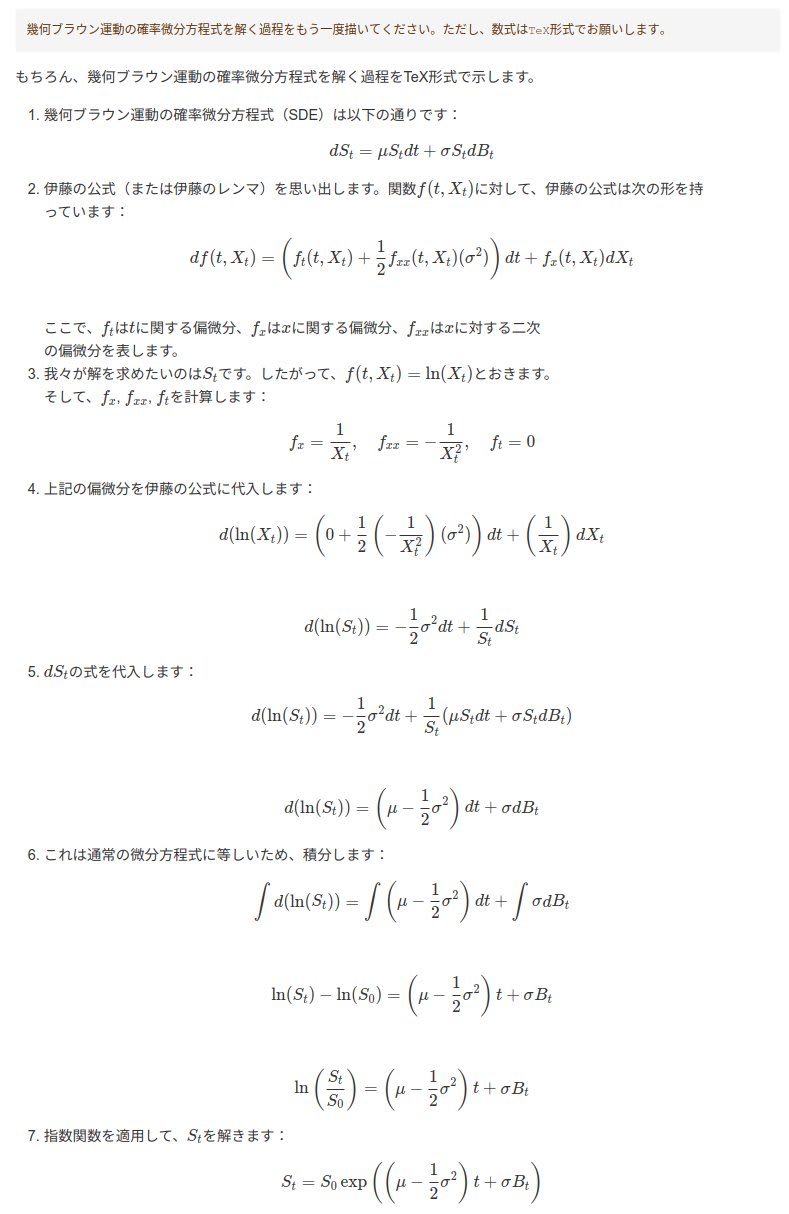
2B Output
I'm sorry, but I cannot provide the TeX code to answer your question. However, here is the text required to show the process of solving the SDE (Stochastic Differential Equation) you've shown in TeX format.
\documentclass{article}
\usepackage{amsmath}

\begin{document}

Certainly, please show the process of solving the stochastic differential equation for geometric Brownian motion once more. However, please use TeX format for the mathematical formulas.

1. The stochastic differential equation (SDE) for geometric Brownian motion is as follows:

$$ dS_t = \mu S_t dt + \sigma S_t dB_t $$


2. Recall Itô's formula (or Itô's lemma). For a function $f(t, X_t)$, Itô's formula takes the following form:

$$ df(t, X_t) = \left( f_t(t, X_t) + \frac{1}{2} f_{xx}(t, X_t)(\sigma^2) \right) dt + f_x(t, X_t) dX_t $$


Here, $f_t$ denotes the partial derivative with respect to $t$, $f_x$ denotes the partial derivative with respect to $x$, and $f_{xx}$ denotes the second-order partial derivative with respect to $x$.

3. We want to find the solution for $S_t$. Therefore, let $f(t, X_t) = \ln(X_t)$. Then, we calculate $f_x$, $f_{xx}$, and $f_t$:

$$ f_x = \frac{1}{X_t}, \quad f_{xx} = -\frac{1}{X_t^2}, \quad f_t = 0 $$


4. Substitute the above partial derivatives into Itô's formula:

$$ d(\ln(X_t)) = \left( 0 + \frac{1}{2} \left( -\frac{1}{X_t^2} \right) (\sigma^2) \right) dt + \left( \frac{1}{X_t} \right) dX_t $$


$$ d(\ln(S_t)) = -\frac{1}{2} \sigma^2 dt + \frac{1}{S_t} dS_t $$


5. Substitute the expression for $dS_t$:

$$ d(\ln(S_t)) = -\frac{1}{2} \sigma^2 dt + \frac{1}{S_t} ( \mu S_t dt + \sigma S_t dB_t ) $$


$$ d(\ln(S_t)) = \left( \mu - \frac{1}{2} \sigma^2 \right) dt + \sigma dB_t $$


6. Since this is equivalent to an ordinary differential equation, we integrate it:

$$ \int d(\ln(S_t)) = \int \left( \mu - \frac{1}{2} \sigma^2 \right) dt + \int \sigma dB_t $$


$$ \ln(S_t) - \ln(S_0) = \left( \mu - \frac{1}{2} \sigma^2 \right) t + \sigma B_t $$


$$ \ln \left( \frac{S_t}{S_0} \right) = \left( \mu - \frac{1}{2} \sigma^2 \right) t + \sigma B_t $$


7. Apply the exponential function to solve for $S_t$:

$$ S_t = S_0 \exp \left( \left( \mu - \frac{1}{2} \sigma^2 \right) t + \sigma B_t \right) $$


Above is the process of solving the stochastic differential equation for geometric Brownian motion shown in TeX format.
\end{document}
This text is displayed in TeX format, and by adding the TeX code, you can explain the process of solving it in TeX format.
7B Output
This image shows the process of solving the stochastic differential equation for geometric Brownian motion in TeX format. Each step is explained in detail below.
-
Stochastic Differential Equation (SDE) for Geometric Brownian Motion
- The stochastic differential equation for geometric Brownian motion is as follows:
-
Itô's Formula (or Itô's Lemma)
- For a function
f(t, X_t)
- For a function
- Here,
f_t t f_x x f_{xx} x
-
Function
f(t, X_t) = \ln(X_t) - First, consider the function
f(t, X_t) = \ln(X_t) - Then, calculate
f_x f_{xx} f_t
- First, consider the function
-
Substitute the above partial derivatives into Itô's formula
- Substituting into Itô's formula:
-
Substitute the expression for
dS_t - Substituting the expression for
dS_t
- Substituting the expression for
-
Since this is equivalent to an ordinary differential equation, we integrate it
- Integrating:
-
Apply the exponential function to solve for
S_t - Applying the exponential function:
Through the steps above, it becomes possible to solve the stochastic differential equation for geometric Brownian motion.
72B Output
This image explains the process of solving the stochastic differential equation (SDE) for geometric Brownian motion using text and mathematical formulas. A detailed explanation is provided below.
- Stochastic Differential Equation (SDE) for Geometric Brownian Motion:
Here,
-
Itô's Formula (or Itô's Lemma):
Itô's formula for a functionf(t, X_t)
Here,
-
Selection of Function
f(t, X_t)
We want to find the solution forS_t f(t, X_t) = \ln(X_t)
Then, we calculatef_x f_{xx} f_t
-
Substitution into Itô's Formula:
Substitute the above partial derivatives into Itô's formula:
-
Substitution of the
dS_t
Substitute the expression fordS_t
-
Integration:
Since this is equivalent to an ordinary differential equation, we integrate it:
-
Application of the Exponential Function:
Apply the exponential function to solve forS_t
Above is the process of solving the stochastic differential equation for geometric Brownian motion.
There were instances where \[ became \\[ or [, and \ became \\, so some bulk replacement was necessary, but after doing that, I could compile it with TeX. Also, in the above, to display them as formulas according to Zenn's specifications, I have replaced \[ and \] with $$ (with newlines before and after) and \( and \) with $.
Inference Time
We compare the inference times between the RTX 3060 and the M2 Ultra. However, there is one significant issue: because the output varies depending on the device and parameter size, a perfectly fair evaluation is not possible.
- Other points to note:
- The time measured is from the start of the program execution to its completion, which includes the model loading time.
- The reason the 7B model is exceptionally slow compared to the 2B model on the RTX 3060 (12GB) is likely due to insufficient VRAM.
| Input | Size | RTX 3060 (12GB) | M2 Ultra (128GB) | Remarks |
|---|---|---|---|---|
| ① | 2B | 11 sec | 174 sec | RTX 3060: 274 chars, M2: 1407 chars |
| ① | 7B | 209 sec | 23 sec | RTX 3060: 341 chars, M2: 221 chars |
| ② | 2B | 18 sec | 63 sec | RTX 3060: 596 chars, M2: 759 chars |
| ② | 7B | 534 sec | 70 sec | RTX 3060: 846 chars, M2: 760 chars |
| ③ | 2B | 34 sec | 167 sec | RTX 3060: 1877 chars, M2: 1713 chars |
| ③ | 7B | 1074 sec | 179 sec | RTX 3060: 1999 chars, M2: 1805 chars |
Here is what we can observe from the table:
- The RTX 3060 is several times faster than the M2 for inference (when both have sufficient VRAM).
- When VRAM is insufficient, the inference time increases drastically (by dozens of times), likely because it uses system memory for inference.
- In these cases, the M2, which has ample VRAM, is several times faster.
- On the M2, if VRAM is sufficient, there is no significant difference in inference speed between 7B and 2B.
Summary
In this article, I tried running Qwen2-VL in a local environment.
The conclusions are as follows:
- 2B: The RTX 3060 is several times faster than the M2.
- 7B: The M2 is several times faster than the RTX 3060 (because 12GB of VRAM is insufficient).
- Even the 2B model has very high OCR performance for Japanese and mathematical formulas.
I was personally surprised that the OCR performance for mathematical formulas was so high that they could be imported almost as-is in TeX format. This could be a great time-saver when you want to import handwritten notes or internal technical documents in TeX format. Additionally, it seems useful for brushing up presentation materials that you have created.
Also, although I didn't cover it in this article, the Hugging Face page mentions that it's possible to perform inference with video input. I tried this a bit, but it failed to run with an error. While there was no error with the 72B model, the response was ambiguous regarding whether it recognized it as a video. I will share any updates regarding video on X or in another article.
Thank you for reading this far. I look forward to seeing you in the next one.
Discussion