iTranslated by AI
[Plot] Basic Usage of pheatmap



Materials I prepared for a workshop. Since there aren't many Japanese resources for pheatmap, I'm sharing them here.
install.packages("pheatmap")
library(pheatmap)
Basic Usage
Simply pass a numeric-only matrix to the pheatmap() function. You will get an error if character columns are included.
For example, in the iris dataset, the 5th column is text, so we use columns 1 through 4.
pheatmap(iris[,1:4])

By just specifying the matrix, colors are assigned to the range of values (minimum to maximum), and samples and columns are reordered based on hierarchical clustering.
List of Arguments
I will explain these in the order of argument name, default value, and description. There is a lot of information, so feel free to use this as a reference dictionary for specific parts.
Basic Parts
-
mat:
A numeric matrix to be used for the plot. Data frames can also be used, but columns with non-numeric data will cause an error. Therefore, store information like sample names in the row or column names of the matrix. For example, gene names for rows and sample names for columns.
-
color:
colorRampPalette(rev(brewer.pal(n = 7, name ="RdYlBu")))(100)
A vector of color information. By default, 100 colors are prepared using the RdYlBu palette from the RColorBrewer package.
-
breaks: NA
A vector of values to which colors are assigned. Since thecolor=argument provides 100 colors by default, specifying a vector of 100 values will map each value to a color. If not specified, the values for color assignment are automatically determined based on the minimum and maximum values in the matrix.
-
scale:
"none"
Centers (mean to 0) and scales (standard deviation to 1) the input data. Normalization is performed by row using "row" or by column using "column".
Clustering
Clustering
-
cluster_rows/cluster_cols:
TRUE
Specifies whether to perform hierarchical clustering by row or by column using TRUE/FALSE. Since the default isTRUE, explicitly set it toFALSEif you do not want to perform clustering.
- Note: If the data contains NA values, a heatmap can still be generated, but clustering cannot be performed, so set this to
FALSE. Also set toFALSEif the data consists of only 1 row or 1 column.
-
clustering_distance_rows/clustering_distance_cols:
"euclidean"
The method for calculating the distance matrix used in hierarchical clustering. This serves as a metric for similarity between data points. Euclidean distance is used by default. Specifying"correlation"will use Pearson correlation.
-
clustering_method:
"complete"
The algorithm used for hierarchical clustering. Since it uses thehclustpackage internally, any method specifiable inhclustcan be used.
"complete": Complete-linkage clustering."single": Single-linkage clustering."average": Unweighted Pair Group Method with Arithmetic Mean (UPGMA)."centroid": Centroid method."median": Median method."ward.D"/"ward.D2": Ward's method (useward.Dfor Euclidean distance andward.D2for squared Euclidean distance).
-
clustering_callback:
identity2
Rarely used. Example usage: https://stackoverflow.com/questions/54762405/pheatmap-re-order-leaves-in-dendogram
-
kmeans_k: NA
The number of clusters for k-means clustering. This is a non-hierarchical clustering method.
-
cutree_rows/cutree_cols:
0
The number of clusters into which the hierarchical clustering should be divided for display. It uses thecutree()function from thehclustpackage.
Graphical Parameters of the Plot
Graphical Parameters of the Plot
-
show_rownames/show_colnames:
TRUE
Whether to display row names and column names in the heatmap.
-
main: NA
Text to be displayed as the title of the heatmap.
-
fontsize:
10:
Overall font size.
-
fontsize_row/fontsize_col:
fontsize
Font size for row and column names. If not specified, follows thefontsize=argument.
-
angle_col:
270
Angle for column names (0, 45, 90, 270, 315).
-
border_color:
"grey60"
The color of cell borders in the heatmap. Only applied when the data volume is small.
-
cellwidth/cellheight: NA
Used to specify fixed width and height for heatmap cells.
-
treeheight_row/treeheight_col:
50
The display size of the dendrogram.
-
legend:
TRUE
Whether to display the legend.
-
legend_breaks: NA
A vector specifying breakpoints for the legend.
-
legend_labels: NA
A vector specifying labels to be displayed at the legend breakpoints.
-
gaps_row/gaps_col: NULL
The width of gaps when the heatmap is partitioned. For example, if there are 100 data points, specify locations for gaps likec(5,20,40,80).
-
labels_row/labels_col: NA
A vector for custom labeling without using the row/column names of the input matrix.
-
filename: NA
File path to export the heatmap. Supports extensions like png, pdf, tiff, bmp, and jpeg.
-
width/height: NA
The overall width and height of the heatmap.
-
silent:
FALSE
Whether to display the heatmap in the R Viewer.
-
na_col:
"#DDDDDD"
The color for cells containing NA values.
Heatmap Annotation
Heatmap Annotation
-
annotation_row/annotation_col: NA
Data frames used for adding annotations to the heatmap.
-
annotation_colors: NA
A list for specifying the colors of the heatmap annotations.
-
annotation_legend:
TRUE
Whether to display the legend for annotations.
-
annotation_names_row/annotation_names_col:
TRUE
Whether to display the names of the annotations.
-
drop_levels:
TRUE
Whether to keep unused factor levels in the legend.
Displaying Values in Heatmap Cells
Displaying Values in Heatmap Cells
-
display_numbers:
FALSE
Specifies whether to display values in each cell of the heatmap. It is also possible to display text by specifying a data frame with the same row and column names as the input matrix.
-
number_format:
"%.2f"
Format for the labels displayed in cells, such as decimal places.
-
number_color:
"grey30"
Color of the labels displayed in cells.
-
fontsize_number:
0.8
Font size of the labels displayed in cells.
Plot Colors
The default heatmap colors are a vector of 100 color codes, generated from the RColorBrewer package palette.
library(RColorBrewer)

colorRampPalette(rev(brewer.pal(n = 7, name ="RdYlBu")))(100)

Default color vector
The colorRampPalette() function returns a function that creates a gradient color vector from a specified color vector. By specifying the number of colors you want in the resulting function, you can obtain a vector of that many color codes.
For example, you can expand the three colors blue, white, and red into 100 colors as follows:
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         color = colorRampPalette(c("blue","white","red"))(n=100)
         )

Providing fewer colors in the vector reduces expressiveness. On the other hand, this can sometimes make interpretation easier through binning.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         color = colorRampPalette(c("blue","white","red"))(n=10)
         )

When only 10 colors are provided
Scaling Data
In the case of the iris dataset, the range of values differs for each item, which can make the data difficult to visualize on the same scale. Using the scale= option allows you to display the data with the mean of each column (or each row) scaled to 0 and the standard deviation (SD) scaled to 1.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column")

Scaling data by column
Scaling by item (column) makes it easier to see differences between samples (rows) within a single item.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column")

Scaling data by row
Scaling within one sample (row) highlights which items (columns) are relatively higher for that specific sample.
In the iris data, the value ranges differ significantly between columns, so this scaling makes those differences sharp, though it may obscure differences between samples.
Heatmap Annotation
If additional information is available for each sample or each item, it can be displayed on the left or top of the heatmap. This can include character information in addition to numerical values.
Annotation information should be prepared separately as a data.frame. For sample (row) annotations, prepare a data.frame with sample names as row names and annotation categories as columns. For item (column) annotations, also prepare a data.frame with item names as row names and annotation categories as columns.
- Note: If row names are missing (just numeric row indices), it will not work correctly, so define the matrix's row and column names in advance.
Here, we set the row names of the matrix as "IDXX" as follows:
demo <- iris[1:4]
rownames(demo) <- paste0("ID", rownames(demo))
Then, prepare an annotation data.frame with the same row names. Here, we use the 5th column, Species, from the iris dataset.
anno <- data.frame(
  row.names = rownames(demo),
  Species = iris$Species
)

Data.frame for row annotations
Specify this data.frame in the annotation_row= argument.
pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno
         )
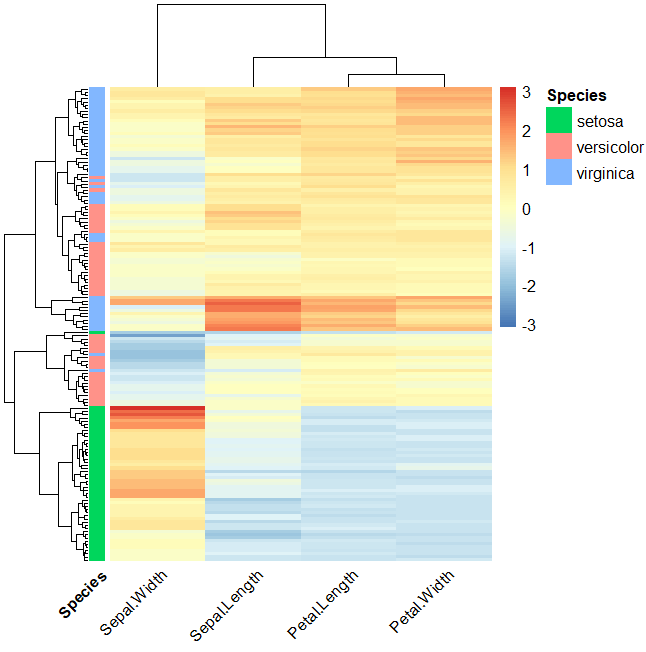
Displaying sample Species information as an annotation
Let's also try adding annotation information to the columns. To do this, prepare a new data.frame specifically for the columns.
Place the column names of the matrix as the row names of the annotation data.frame.
anno_col <- data.frame(
  row.names = colnames(demo),
  var1=c("Sepal","Sepal","Petal","Petal"),
  var2=c("Length","Width","Length","Width")
  )

Data.frame for column annotations
Specify this in the annotation_col= argument.
pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno,
         annotation_col = anno_col
         )

Annotation Colors
To specify the colors for each annotation, you need to create a list summarizing the color information. In this list, set the name attributes to the annotation names (e.g., Species, var1, var2 from the example above) and the elements to named color vectors. You can specify row and column annotation information together in this single list.
For Character/Factor Values
As an example, let's specify the colors for Species. Create a color vector with the required number of colors and assign the corresponding levels to its name attribute. The elements represent the colors, and the name attributes represent the levels.
# Create a color vector
species_color <- c("red","blue","green")
# Assign the corresponding levels to the name attribute of the vector
names(species_color) <- c("setosa", "versicolor", "virginica")
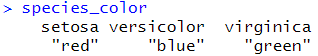
Color vector for annotations
Then, organize this into a list. Assign the corresponding annotation name to the list's name attribute.
anno_colors <- list(Species = species_color)
Pass the list of annotation color vectors to the annotation_colors= argument.
pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno,
         annotation_col = anno_col,
         annotation_colors = anno_colors
         )

Add the color information for column annotations to the same list.
anno_colors$var1 <- c("Petal"="white", "Sepal"="black")
anno_colors$var2 <- c("Length"="gray", "Width"="lightgray")

pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno,
         annotation_col = anno_col,
         annotation_colors = anno_colors
         )

For Numerical Values
For numerical values, you only need to provide a color vector without name attributes.
anno$group <- rep(1:5, each=30)
anno_colors$group <- c("white","lightgreen","green","darkgreen","black")

pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno,
         annotation_colors = anno_colors
         )

Gradient color vectors can be easily prepared using the colorRampPalette() function.
# Create dummy continuous values for demonstration
anno$dummy <- sample(1:100, size=150, replace = TRUE)

anno_colors$dummy <- colorRampPalette(c("blue","white","red"))(100)

pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         annotation_row = anno,
         annotation_colors = anno_colors
         )

Hierarchical Clustering
By default, hierarchical clustering is performed for both rows and columns. Internally, it uses the dist() function to create a distance matrix based on the Euclidean distance between data points, and the hclust() function for hierarchical clustering using the complete-linkage method. If the data volume is very large, hierarchical clustering can take some time.
Clustering Methods
Changing the clustering method can noticeably change the results. There is no single "correct" method, so feel free to use whichever one you prefer.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "average")

average
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D")

ward.D
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2")

ward.D2
Splitting the Plot Based on Hierarchical Clustering
Hierarchical clustering creates a dendrogram based on the similarity of each sample and item. Following each line leads to a single data point, meaning that as many clusters can be created as there are data points. By cutting the dendrogram at a specified number of clusters, you can group them into clusters containing multiple data points.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         cutree_rows = 3
         )

pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         cutree_rows = 5
         )

Just as with samples, you can also split items into clusters.
pheatmap(iris[1:4],
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         cutree_rows = 5,
         cutree_cols = 2)

Obtaining the Sample/Item Order Displayed on the Heatmap
Heatmaps often deal with large amounts of information, so row and column names are frequently hidden. However, it can be problematic if you cannot verify the sample or item names after they have been reordered based on hierarchical clustering.
To obtain this information, save the output of pheatmap() to an object and access the hierarchical clustering information within that object (which is a list type).
# Use data with row names for clarity in the demo.
demo <- iris[1:4]
rownames(demo) <- paste0("ID", rownames(iris))

# Save the pheatmap result to object p
p <- pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         silent = T
         )

pheatmap object
The "tree_col" and "tree_row" sections hold the hierarchical clustering information for columns and rows, respectively.

Hierarchical clustering information within the pheatmap object
Furthermore, tree_row$labels contains the matrix row names, and tree_row$order contains the row sequence as displayed in the plot.

Row names and their display order
In other words, by using the order information to index the row names, you can obtain the row names in the order they are displayed on the heatmap.
p$tree_row$labels[p$tree_row$order]

Row names reordered to match the heatmap display
Obtaining Cluster Numbers for Each Data Point
I will show you how to check which sample belongs to which cluster after splitting the data into clusters.
Save the pheatmap() output to an object, retrieve the hierarchical clustering information from that object (list type), and then use the cutree() function to perform cluster splitting.
cutree(p$tree_row,k = 5)
You will get a vector of cluster numbers for each sample. The name attributes contain the row names of the matrix.
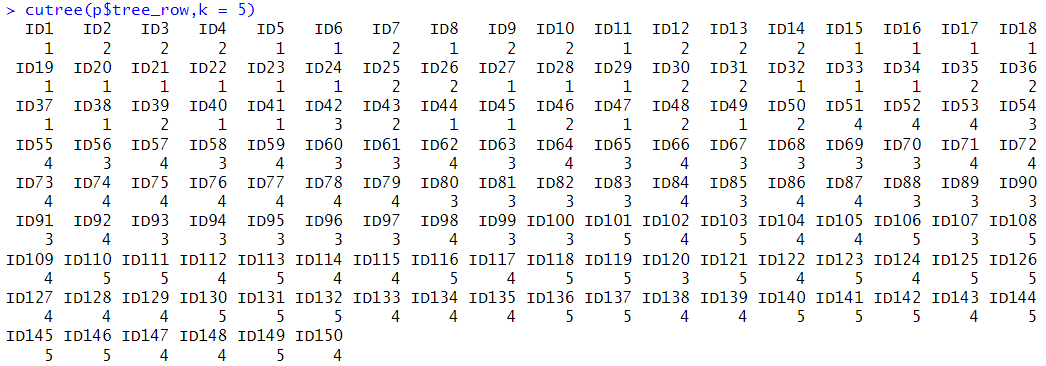
The cluster each sample belongs to when divided into 5 clusters
If you reorder them according to the display order of pheatmap, you can verify that the samples are lined up with the same cluster numbers.
cluster <- cutree(p$tree_row,k = 5)
cluster[p$tree_row$order]
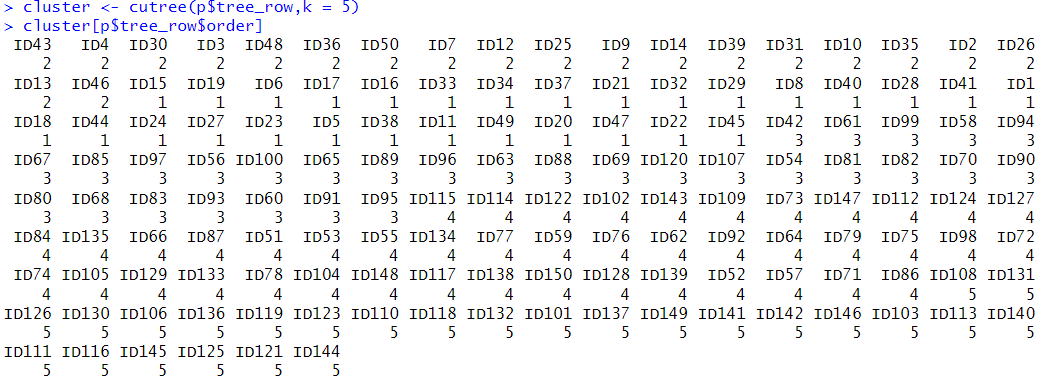
Heatmap display order and cluster numbers
Note: Keep in mind that the display order in pheatmap is not necessarily in ascending order of cluster numbers.
Displaying Cluster Numbers as Annotations on the Heatmap
Since it can be difficult to visually verify the correspondence between samples and cluster numbers alone, I will show an example of displaying them as heatmap annotations.
demo <- iris[1:4]
rownames(demo) <- paste0("ID", rownames(iris))
p <- pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         silent = T
         )

anno <- data.frame(
  row.names = rownames(demo),
  # Cluster numbers are numeric. Convert to character so they are not treated as continuous values.
  cluster = as.character(cutree(p$tree_row, k = 5)[rownames(demo)])
  )

pheatmap(demo,
         show_rownames = F,
         angle_col = 45,
         scale = "column",
         clustering_method = "ward.D2",
         cutree_rows = 5,
         annotation_row = anno
         )

K-means Clustering
K-means clustering can be performed simply by specifying the number of clusters in the kmeans_k= argument. This method is only applied to rows, so if you want to execute it on columns, transpose the matrix with t() before passing it.
- Note: K-means results change every time it is run.
pheatmap(iris[1:4],
         angle_col = 45,
         kmeans_k = 5
         )

K-means results can also be accessed by saving the pheatmap() output to an object.
p2 <- pheatmap(iris[1:4],
         angle_col = 45,
         kmeans_k = 5,
         )
p2$kmeans

Tips
Transposing the Matrix
Transpose the matrix using the t() function. Note that in this case, the row and column arguments will also be reversed.
pheatmap(t(demo),
         show_colnames = F,
         angle_col = 45,
         scale = "row",
         annotation_col = anno,
         annotation_row = anno_col,
         annotation_colors = anno_colors
         )

Visualizing 1-Column or 1-Row Data
By default, hierarchical clustering is performed. However, if there is only one row or one column, hierarchical clustering cannot be conducted, resulting in an error.

Error in hclust(d, method = method):
must have n >= 2 objects to cluster
Visualization is possible by setting cluster_rows= or cluster_cols= to FALSE to prevent hierarchical clustering.
pheatmap(iris[,1,drop=FALSE],
         cluster_cols = FALSE,
         show_rownames = F
         )

When Data Contains NA
If there are some NA values, the process proceeds without error. NA locations are displayed in gray.
demo2 <- demo
demo2[c(1,5,10,25,30,50,100),c(2,4)] <- NA

pheatmap(demo2)
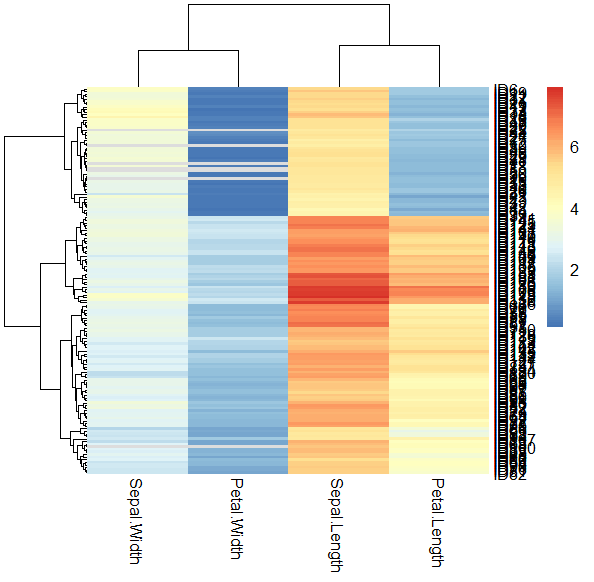
However, if all items in a sample are NA, an error occurs.
demo3 <- demo
demo3[c(1,10,100),] <- NA

pheatmap(demo3)
Error in hclust(d, method = method): NA/NaN/Inf in foreign function call (arg 10)
This error is also due to the inability to perform hierarchical clustering, so visualization is possible by setting hierarchical clustering to FALSE.
pheatmap(demo3, cluster_rows = F)

Preventing Colors from Being Distorted by Outliers
Displaying Marks on the Heatmap
Editing Plot Elements like the Legend
You can call the pheatmap() function using the ComplexHeatmap package. This approach allows you to use ComplexHeatmap commands for plot editing.
Discussion