iTranslated by AI
Building a Chatbot Specialized in Project Knowledge




TL;DR
- Try providing external knowledge to an LLM using Retrieval-Augmented Generation (RAG)
- Technically, combining a simple index from LlamaIndex with LangChain
- Create verification data and build a mechanism for an improvement loop
Motivation
Reducing the time cost of responding to inquiries
By identifying the problems that occurred before the introduction of the chatbot, we clarify the ideal state we want to achieve.
In our company, we mainly use Slack as a communication tool with internal members and clients, but as the number of projects has increased, the time spent responding to inquiries has grown.
Inquiry content can be broadly classified into three categories:
- Questions about product specifications
- Requests for additional features, etc.
- Bug reports
For the latter two, "requests" and "bug reports," we can reduce the subsequent back-and-forth by establishing a certain format. In other words, even before talking about AI, we can easily solve these pain points by utilizing existing tools.
However, responding to the first category, "questions," requires a bit of ingenuity. (While it's easy to say "please check the documentation," we want to avoid imposing that burden on the client if possible.)
As a project grows, the amount of documentation to check increases accordingly. To avoid a situation where knowledge becomes siloed and only specific people (like PdMs) can understand and explain the whole picture, I thought some kind of systematic solution was necessary.
Wanting to build a complete RAG-based mechanism
The rest was purely out of technical curiosity; I wanted to get a hands-on feel for what can be achieved with RAG 😎
What I Built
Here is an image of the overall structure of RAG.
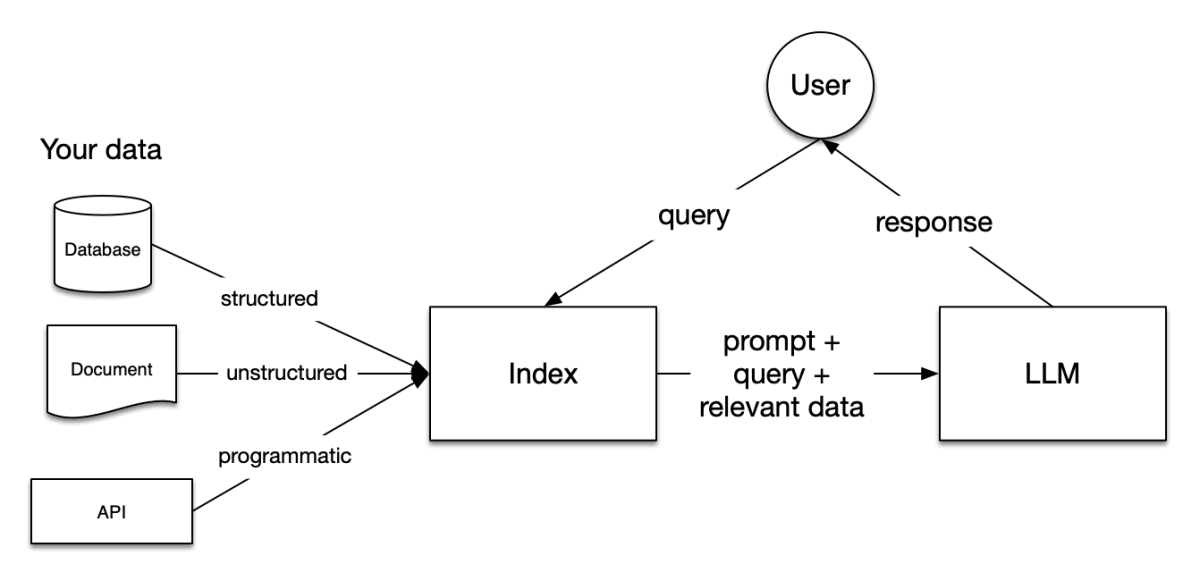
Overall structure of RAG[1]
Relevant data is extracted from the corpus (Your data) based on the user's query, and the result is obtained by passing the prompt along with the original query to the LLM.
I designed it following the development steps for RAG applications found in the LlamaIndex documentation.
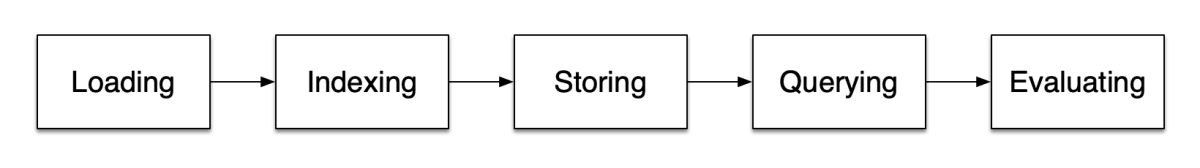
Development steps for RAG[1:1]
Loading
First, ingest data from external data sources into the RAG pipeline.
I think using document data managed within the project is the simplest and fastest approach. We mainly use Notion, but you should look for data loaders on LlamaHub or LangChain that fit your team's tools.
If you just want to bring in raw data, copying and pasting would suffice, but this time I also wanted to evaluate the RAG pipeline in the Evaluating step. Therefore, I created a dataset for evaluation; the details are in the Appendix.
If you don't have raw data and want to evaluate the pipeline you've developed for now, you can use public data that comes with verification datasets. Below is one of the datasets used for benchmarks in the field of information retrieval called BeIR.
About the FiQA dataset by ChatGPT
The "FiQA - Financial Opinion Mining and Question Answering" dataset is a dataset built primarily around financial text data, specializing in tasks such as Opinion Mining and Question Answering. This dataset aims to promote the application of Natural Language Processing (NLP) in the financial sector.
Since this dataset includes the original corpus, I was also able to test the logic for extracting contexts containing the user's queried questions from source data such as a DB.
By the way, there are few public Japanese datasets. One thing to be careful about when using English datasets is performance degradation due to language or domain differences. Therefore, pilot testing is necessary before introducing the developed pipeline to a project, but I believe it is meaningful to use them in terms of creating a mechanism for rapid iteration first.
Code
HuggingFace's dataset is loaded as LlamaIndex Documents.
from datasets import load_dataset
from langchain.schema import Document
from llama_index.schema import Document as LlamaIndexDocument

# columns: _id, title, text
fiqa_corpus = load_dataset("BeIR/fiqa", "corpus")

# Convert to LlamaIndex Document format
docs: list[LlamaIndexDocument] = []
for data in fiqa_corpus["corpus"]:
  langchain_doc = Document(page_content=data["text"], metadata={"_id": data["_id"]})
  docs.append(LlamaIndexDocument.from_langchain_format(langchain_doc))
Indexing
Create a data structure that allows for cross-searching of the data sources loaded in the Loading step.
Although only a simple VectorStoreIndex is used this time, improving accuracy can be expected by designing the index according to the data structure of the corpus. [2]
Naturally, if the original source project documents are updated, this index also needs to be recreated. Therefore, when operating in production, the system design of the index update flow must be considered. I have described what I investigated regarding these operations in the Appendix, so if you manage your documents in Notion, please refer to it!
Code
from langchain.chat_models import ChatOpenAI
from langchain.embeddings import OpenAIEmbeddings
from llama_index import LLMPredictor
from llama_index.service_context import ServiceContext
from llama_index.storage.storage_context import StorageContext
from llama_index.node_parser.text.sentence import (
    DEFAULT_CHUNK_SIZE,
    SENTENCE_CHUNK_OVERLAP,
    SentenceSplitter,
)
from llama_index.callbacks.base import CallbackManager
from llama_index.vector_stores import PineconeVectorStore, SimpleVectorStore

# Define it explicitly to allow changing parameters after evaluation
llm_predictor = LLMPredictor(ChatOpenAI(api_key=OPENAI_API_KEY))
embed_model = OpenAIEmbeddings(api_key=OPENAI_API_KEY)
node_parser = SentenceSplitter(
    chunk_size=DEFAULT_CHUNK_SIZE,
    chunk_overlap=SENTENCE_CHUNK_OVERLAP,
    callback_manager=CallbackManager(),
)
service_context = ServiceContext.from_defaults(
    llm_predictor=llm_predictor,
    embed_model=embed_model,
    node_parser=node_parser,
)

vector_store = SimpleVectorStore()
storage_context = StorageContext.from_defaults(vector_store=vector_store)

# Create Index
index = VectorStoreIndex.from_documents(
    docs,
    storage_context,
    service_context,
    show_progress=True
)
I pass the OpenAI API key explicitly when creating the model instance. While embedding it in environment variables would make the code cleaner, I do this to prevent obscuring where the API calls are occurring.
Storing
By persisting the created Index to external storage or similar, you can reduce the cost of generating embeddings and indexes from the next run onwards.
Code
# Persist to local disk
index.storage_context.persist(persist_dir="./path/to/folder")

# Load from local disk
from llama_index import load_index_from_storage

vector_store = SimpleVectorStore.from_namespaced_persist_dir(persist_dir="./drive/MyDrive/storage_context")
storage_context = StorageContext.from_defaults(vector_store=vector_store)
index = load_index_from_storage(storage_context, service_context)
Querying
Submit a query against the index and obtain search results.
Code
query_engine = vector_index.as_query_engine()
ourput = query_engine.query("How to deposit a cheque issued to an associate in my business into my business account?")
output.response # response string
Evaluating
This is an important step to evaluate the accuracy of the developed pipeline. RAG pipeline evaluation is often broadly divided into Retrieval and Generation axes[3].
Retrieval
Evaluates whether the context relevant to the query is appropriately extracted from the corpus. This refers to the accuracy of the "relevant data" extracted from "Your data" in the overall RAG diagram.
- Recall: How much of the relevant items are included in the search results among all relevant items.
- Precision: The ratio of relevant items included in the search results.
There are also metrics that consider the ranking of relevant items, but I will leave the detailed explanation to other articles.
Generation
Evaluates whether the response uses the content of the context. This refers to the accuracy of the "response" text in the overall RAG diagram.
- Relevancy: To what extent the search results match the query, considering the context.
- Faithfulness: To what extent the search results match the context.
In other words, it quantitatively determines whether the search results are giving irrelevant answers or making up lies based on the extracted context.
What's interesting is that LLMs are also utilized for this "quantitative" judgment. Since contexts are text arrays rather than numbers, and comparing them with search results manually doesn't scale, the evaluation is entrusted to an LLM judge.
By performing quantitative evaluation and analysis of each measure—such as the accuracy improvement strategies mentioned briefly in the Index step—based on the metrics measured here, you can refine the pipeline to be more robust! (Hopeful thinking)
Code
This time, I implemented it using Ragas[4], a library for RAG evaluation.
from ragas.langchain import RagasEvaluatorChain
from ragas.metrics import (
    AnswerRelevancy,
    Faithfulness,
    ContextRecall,
    ContextPrecision,
)
from ragas.llms import OpenAI
import pandas as pd

embeddings_model = OpenAIEmbeddings(model="text-embedding-ada-002", openai_api_key=OPENAI_API_KEY)
llm = OpenAI(model="gpt-3.5-turbo-1106", api_key=OPENAI_API_KEY)

faithfulness = Faithfulness(llm=llm)
answer_relevancy = AnswerRelevancy(embeddings=embeddings_model, llm=llm)
context_precision = ContextPrecision(llm=llm)
context_recall = ContextRecall(llm=llm) # need ground_truths

# Create evaluation chains for Ragas in LangChain
eval_chains = {
    m.name: RagasEvaluatorChain(metric=m) for m in [
          faithfulness,
          answer_relevancy,
          context_precision,
          context_recall,
        ]
}

# Calculate the average value for each metric
df_eval = pd.DataFrame(columns=eval_chains.keys())
for question in fiqa_eval["baseline"]["question"]:
  output = qa_chain({"query": question})
  row_eval = {}
  for name, eval_chain in eval_chains.items():
    row_eval[name] = eval_chain(output)[f"{name}_score"]
  df_eval = pd.concat([df_eval, pd.DataFrame([pd.Series(row_eval)])])

# OUTPUT
# ---
# faithfulness         0.822222
# answer_relevancy     0.872568
# context_precision    0.816667
# context_recall       0.812532
df_eval.mean()
Appendix
Creating a dataset for verification
Since the models that power LLM applications have an underlying probabilistic nature, it is important to verify them with test data that matches the production distribution in order to create a more robust model.
The items required for verifying a RAG pipeline are as follows:
| Column | Description |
|---|---|
| question | The question |
| contexts | Data required to generate the answer (relevant data) |
| ground_truths | The correct answer |
| answer | The answer generated by RAG |
While I created the test data manually this time, there are convenient tools available to automatically generate them using existing OSS.
However, the results obtained were not in a state where they could be used as-is due to language issues and other factors, so I implemented it from scratch while using the prompts as a reference.
In Ragas' TestsetGenerator, ground_truths and contexts were created with separate prompts, but I found that having them output together reduced the rate of picking up contexts with weak relationships.
from langchain.llms import OpenAI, OpenAIChat
from langchain.chains import LLMChain
from langchain.prompts import PromptTemplate
from langchain_core.pydantic_v1 import BaseModel, Field
from langchain.output_parsers import PydanticOutputParser
import pandas as pd

class TestDataset(BaseModel):
    question: str = Field(description="question")
    ground_truths: list[str] = Field(description="ground truths")
    relevant_sentences: list[str] = Field(description="relevant sentences")

parser = PydanticOutputParser(pydantic_object=TestDataset)

llm = OpenAI(temperature=0, api_key=OPENAI_API_KEY, model="text-davinci-003")
prompt = PromptTemplate(
    template="""You are a teacher coming up with questions to ask on a quiz.
Given the following document, please generate a question and answer based on that document in Japanese.

In addition, please extract relevant sentences from the provided document that can potentially help your answer.
While extracting candidate sentences you're not allowed to make any changes to sentences from given context.

Document Format:
<Begin Document>
{doc}
<End Document>

Be sure to follow the output instructions and ensure correct JSON format.
Be aware that your results often end up outputting in the middle of a statement.
{format_instructions}

These questions should be detailed and be based explicitly on information in the document. Begin!""",
    input_variables=["doc"],
    partial_variables={"format_instructions": parser.get_format_instructions()},
)
llm_chain = LLMChain(prompt=prompt, llm=llm)

# DataFrame to store the test data
df_baseline = pd.DataFrame()
for i, node in enumerate(nodes):
  try:
    context = node.get_content()
    res = llm_chain.predict(doc=context)
    test_dataset = parser.parse(res)

    row_baseline = {
        "question": test_dataset.question,
        "contexts": test_dataset.relevant_sentences,
        "ground_truths": test_dataset.ground_truths,
    }
    df_baseline = pd.concat([df_baseline, pd.DataFrame([pd.Series(row_baseline)])])
    print(f"Success generate dataset! {i}")
  except Exception:
    # Ignore errors, such as failing to parse the results
    pass
Handling document updates
During production operations, the index needs to be recreated whenever documents are updated. Here, I will briefly introduce some ways to detect changes in pages created in Notion.
- Detect changes or additions to Notion database records using Zapier
- An effective method if documents are managed within a Notion database
- Cannot detect deletions
- Add a column to the Notion database to manage the index creation status
- Statuses like "Before creation", "Created", "Not required", etc.
- Change the status to "Before creation" whenever a document is updated during operations
- Have a periodic batch process check the status and set it to "Created" once processed
- Once Database automations can send notifications to external services other than Slack, the batch mechanism might no longer be necessary 🤔
Once you obtain the IDs of the modified pages through the above methods, you can use the Notion API to retrieve the body text, recreate the index, and save it to external storage.
Summary
As the use of AI advances in the world, the importance of documentation will likely increase even further.
LLM applications, including RAG, involve probabilistic properties, making it difficult to achieve expected results 100% of the time. Therefore, developing version 1 at lightning speed and creating a mechanism to run an improvement loop based on the feedback obtained will lead to maximizing the value provided.
This time, I ended with a simple implementation using LlamaIndex, but I plan to publish the improvements and tips I discovered during operations in a separate article.
See you again!
Discussion