iTranslated by AI
Implementing Full-Text Search for All Zenn Books


Introduction
While full-text search for books is on Zenn's roadmap, currently only title and chapter matching is supported.
Zenn Roadmap · zenn-dev/zenn-community
Is there any way to enable full-text search?
Searching the Manuscript Repository Directly
Zenn allows you to connect your posting data with a GitHub account.
Therefore, if the manuscript of the book you want to search is in a public GitHub repository, you can perform a full-text search on GitHub.

(Searching the repository for "Chakra UI Walking Guide & Tips")
However, you cannot search across multiple books, and this method is unavailable if there is no GitHub integration or if there is no public repository.
Since I wanted to search across multiple books simultaneously, I looked for an alternative method.
Crawling Body Data Using Internal APIs
According to Zenn's roadmap, there is a thread regarding API provision, but the timing is still TBD.
I will address this issue by accessing site data in compliance with the Terms of Service between Zenn and myself (as a user).
I will omit the specifics as the goal is not to disclose details of reverse engineering, but the following information can be retrieved from the site's internal API:
- List of books
- List of chapters within a book
- List of text within a chapter
From this, it seems theoretically possible to search across multiple books by searching for "text" and tracing back to the "chapter" and "book" it belongs to.
However, hosting a full-text search system is generally costly. Isn't there a more casual way to build this?
Search Index Using Google Drive API
Google Drive API provides a full-text search function for stored files.
Search for files and folders | Google Drive API | Google Developers
Additionally, you can attach metadata in a key=value format called "properties" to each file.
Properties | Google Drive API | Google Developers
By combining these two, you can create the following workflow:
- Save the text of a chapter into a file and upload it.
- Attach the book and chapter IDs to the properties.
- Search all files using the Google Drive API.
- Retrieve the book and chapter IDs from the search results.
The following sections explain the specific application implementation using JavaScript.
Issuing a Service Account
Issue a Service Account for accessing the Google Drive API to upload and search files from https://console.cloud.google.com/iam-admin/iam.
Next, create a root folder that can be read and written by this Service Account from https://drive.google.com/drive/my-drive. This should be done using your own Google account, not the Service Account.
Grant edit permissions for this folder to the Service Account's email address.

Generate a key for this Service Account to use in your program.
Creating and managing service account keys | Cloud IAM Documentation | Google Cloud
Uploading to Google Drive
We will use the Google APIs Node.js Client.
Initialization
const {google} = require('googleapis');

const auth = new google.auth.GoogleAuth({
    credentials: {
        client_email: SERVICE_ACCOUNT_EMAIL,
        private_key: `-----BEGIN PRIVATE KEY-----\n${GOOGLE_PRIVATE_KEY}\n-----END PRIVATE KEY-----`,
    },
    scopes: 'https://www.googleapis.com/auth/drive.file',
});
google.options({auth});
const service = google.drive('v3');
SERVICE_ACCOUNT_EMAIL and GOOGLE_PRIVATE_KEY are included in the JSON of the Service Account key you created earlier.
While you can include them from a JSON file written to disk, I designed it this way to handle secret data via environment variables and process it in-memory for operational considerations.
Folder Creation Function
While the number of Zenn books is small enough that it won't be an issue for this system, Google Drive shared folders have a limit of 500,000 items per folder.
Any single folder in Drive which is not in a shared drive can have a maximum of 500,000 items placed within it.
https://support.google.com/a/answer/2490100
Therefore, it is safer to implement sharding in such automation. In the example below, I created subfolders for each book.
async function createFolder(book) {
    const name = book.user.username + '/' + book.slug
    const exist = await service.files.list({
        q: `name = '${name}' and mimeType = 'application/vnd.google-apps.folder' and '${ROOT_FOLDER_ID}' in parents`,
        fields: 'files(id, name)',
    })
    if (exist.data.files.length > 0) {
        await service.files.delete({fileId: exist.data.files[0].id})
    }

    const bookFolder = await service.files.create({
        requestBody: {
            name,
            mimeType: 'application/vnd.google-apps.folder',
            parents: [ROOT_FOLDER_ID],
        }
    })
    return bookFolder.data
}
Google Drive allows duplicate folder names. To prevent creating two folders when saving the same book multiple times, I delete the existing folder using service.files.delete() .
Upload Function
const assert = require('assert');

async function upload(folder, book, chapter, order=0) {
    assert(chapter.allowed, 'Chapter is not allowed')
    assert(chapter.body_html, 'body_html is not defined')

    const properties = {
        'order': order,
        'book': book.title.slice(0, 40),
        'username': book.user.username,
        'slug': book.slug,
        'chapter_title': chapter.title,
        'chapter_id': chapter.id,
        'chapter_slug': chapter.slug,
        'cover_url': book.cover_image_small_url
            ? book.cover_image_small_url.replace(/^.*(https:\/\/storage.googleapis.com)/, "$1")
            : 'https://zenn.dev/images/book.png',
        'avatar_url': book.user.avatar_small_url.indexOf('storage.googleapis.com') > -1
                ? book.user.avatar_small_url.replace(/^.*(https:\/\/storage.googleapis.com)/, "$1")
                : ''
    }

    const description = chapter.body_html.replace(/(<([^>]+)>)/ig, '').slice(0, 4000)
    const res = await service.files.create(
        {
            requestBody: {
                mimeType: 'application/vnd.google-apps.document',
                parents: [folder.id],
                name: book.title + ' - ' + chapter.title,
                description,
                createdTime: chapter.body_updated_at,
                properties,
            },
            media: {
                mimeType: 'text/html',
                body: chapter.body_html,
            },
        }
    );
    return res.data
}
book.title.slice(0, 40)
book.cover_image_small_url.replace(/.../)
The reason for cutting the character count like this is because properties have a 124-byte limit for UTF-8.
Another point: placing the text of chapter.body_html with HTML removed into the description is a shortcut for easily implementing search result highlighting. I've also trimmed the end here due to character limits...
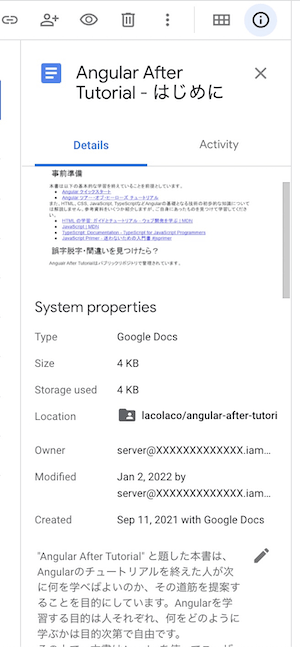
(The first chapter of "Angular After Tutorial" being saved)
Full-text Search Function
async function searchFromDrive(input, opts={}) {
    const {pageToken, username, slug} = opts

    let query = `mimeType = 'application/vnd.google-apps.document' and `
    query += `fullText contains '${input}' and `
    if (username) {
        query += `properties has { key='username' and value='${username}' } and `
    }
    if (slug) {
        query += `properties has { key='slug' and value='${slug}' } and `
    }
    query += 'trashed = false'

    const res = await service.files.list({
        q: query,
        pageToken,
        fields: 'files(id, name, parents, description, properties), nextPageToken',
    });
    const books = filesToBooks(res.data.files, input)
    return {books, nextPageToken: res.data.nextPageToken};
}
Although it's a bit unusual, we dynamically construct a search query that utilizes the property structure to reach the target file. The query syntax is documented below.
Search for files and folders | Google Drive API | Google Developers
The pageToken is for paging as the name suggests. filterToBooks() is omitted as it's an application-specific formatting process.
Also, if you want to match only the list of authors or book titles, you can do so by querying only the properties.
async function searchBooks(input, opts={}) {
    const {pageToken, username} = opts

    let query = `mimeType = 'application/vnd.google-apps.document' and `
    query += `name contains '${input}' and `
    if (username) {
        query += `properties has { key='username' and value='${username}' } and `
    }
    query += 'trashed = false'

    const res = await service.files.list({
        q: query,
        pageToken,
        orderBy: 'createdTime',
        fields: 'files(id, name, parents, description, properties), nextPageToken',
    });
    const books = filesToBooks(res.data.files, input)
    return {books, nextPageToken: res.data.nextPageToken};
}
Building the Frontend
Now that the backend is developed in Node.js, I decided to prepare a web app interface to use it.
I didn't have any specific preferences, so I configured it with Next.js + Cloud Functions and deployed it to Firebase Hosting.
Cloud Functions Part
We'll use the firebase-js-sdk to make the search functions we just created callable from the browser.
const functions = require("firebase-functions");
const {searchBooks, searchChapters} = require("./lib/drive");

exports.search = functions.region('asia-northeast1')
    .https
    .onCall(async (data, context) => {
        const {query, username, slug, pageToken} = data;
        const {auth} = context;
        functions.logger.info(`search: ${query}`, {auth});
        const result = await searchChapters(query, {username, slug, pageToken});
        return result;
    })

exports.searchBooks = functions.region('asia-northeast1')
    .https
    .onCall(async (data, context) => {
            const {query, username, pageToken} = data;
            const {auth} = context;
            functions.logger.info(`search: ${query}`, {auth});
            const result = await searchBooks(query, {username, pageToken});
            return result;
    })
Book Search UI

When a search is executed, the Function we deployed earlier is called.
<form onSubmit={async (event) => {
    event.preventDefault()

    const search = await callableAPI('searchBooks')
    const query = event.target.query.value
    const result = await search({query})
    setBooks(result.data.books)
}}>
    <div className="flex p-2">
        <span className="pr-2">🔍</span>
        <input
            className="pl-2"
            type="text" name={`query`} placeholder="Find Books"/>
    </div>
</form>
Inside callableAPI():
import {connectFunctionsEmulator, getFunctions, httpsCallable} from "firebase/functions";
import {initializeFirebaseApp} from "./firebase";

export async function callableAPI(name) {
    const app = await initializeFirebaseApp()
    const functions = getFunctions(app, 'asia-northeast1')
    if (process.env.NEXT_PUBLIC_FUNCTIONS_EMULATOR_HOST) {
        connectFunctionsEmulator(functions, process.env.NEXT_PUBLIC_FUNCTIONS_EMULATOR_HOST, process.env.NEXT_PUBLIC_FUNCTIONS_EMULATOR_PORT);
    }
    return httpsCallable(functions, name)
}
connectFunctionsEmulator() is a useful tool that calls Functions running on localhost during development.
Full-text Search for Book Chapters
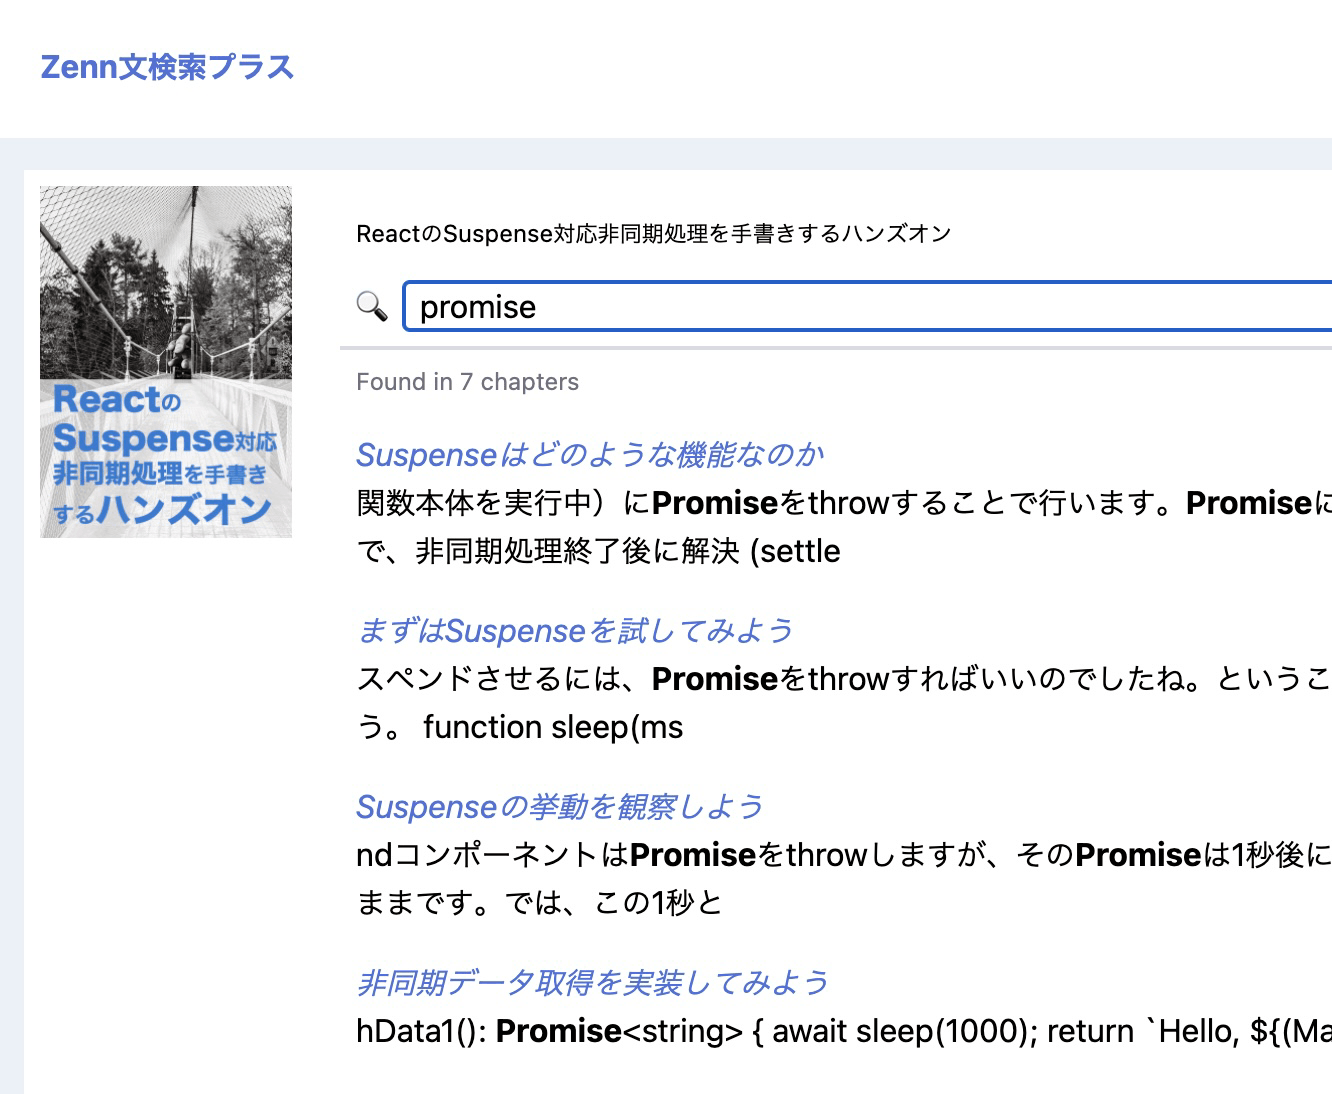
(Searching for "promise" in "Hands-on: Hand-writing Asynchronous Processing for React Suspense")
This also just calls Cloud Functions without doing anything special, but it replaces results matching the description mentioned earlier with bold text to represent highlighting.
// Simple highlighting process
const headRegex = new RegExp('(' + input.split(/\s/).shift() + ')', 'igm')
const index = (file.description || ``).search(headRegex)
const description = index > -1
    ? file.description.slice(index-10, index+90).replace(headRegex, "<strong>$1</strong>")
    : (file.description || ``).slice(0, 100)
The reason for using input.split(/\s/) is to support AND searches.
With this, the "site for full-text searching Zenn books" is complete. This site seems useful, so can it be made available to others?
Issues
However, when making this site public, there is a problem: unless you continuously crawl and update data at short intervals, users will see outdated information (a common challenge in crawler development).
For instance, we must handle cases where "it was free at the time of crawling but became private the next day" or "the book itself was deleted."
There is a risk that "accessing paid content without payment," which is prohibited by the Terms of Service, could be provided to third parties through redistribution using cached data.
Article 4 (Prohibited Matters)
Accessing paid content on this service without payment by any means.
https://zenn.dev/terms
Since these issues apply to all books, it is difficult to address them without delay. While options like "adding a deletion request feature" or "adding a button to manually re-crawl" are possible, they are merely workarounds.
Furthermore, because this relies on Zenn's internal APIs, there is a high probability that the crawler will stop working due to specification changes.
Therefore, I decided to keep this site for personal use only.
Conclusion
Using the Google Drive API, you can easily develop applications with simple full-text search capabilities.
Although I achieved my goal of "full-text searching Zenn books" in a closed environment, I gave up on public release and continuous operation because it would be difficult.
I will wait for the feature to be provided officially or for the Zenn API to be released.
Discussion