iTranslated by AI
[CloudFormation/S3/Lambda] Triggering Lambda from S3 File Uploads: Implementation Guide


1. Introduction
In this article, I would like to create a simple serverless application using AWS Lambda.
The functional image of the implementation is as follows:
- Upload a file to S3
- Execute a Lambda function triggered by the file upload
- Retrieve the content of the uploaded file within the Lambda function
Additionally, we will templatize each resource (S3/Lambda) to enable deployment via CloudFormation.
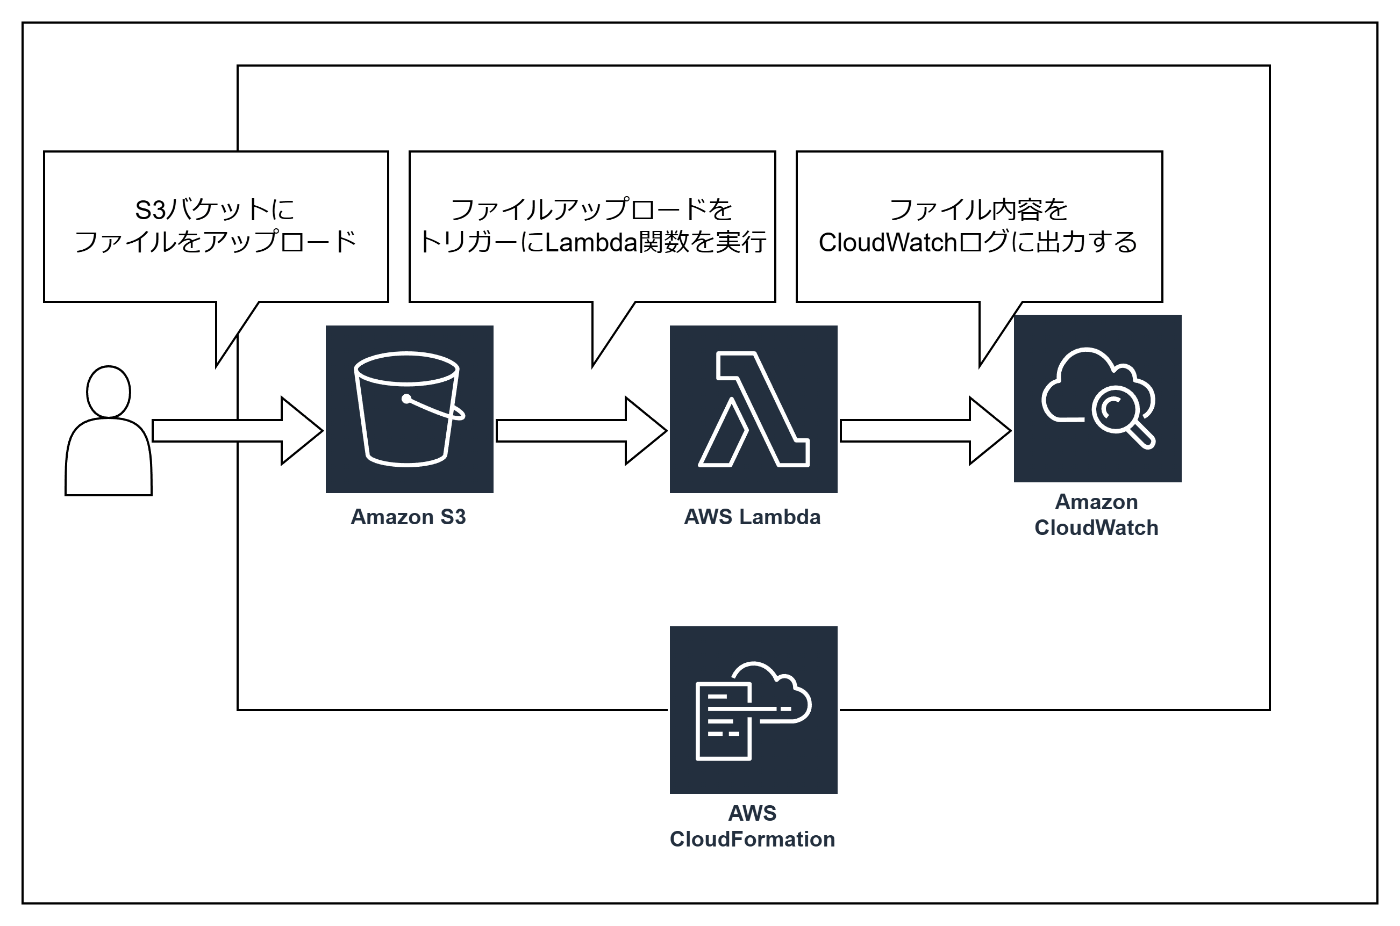
This article consists of two parts: an Implementation Edition and a Deployment Edition.
- Implementation Edition: Focused mainly on Lambda function implementation in Python
- Deployment Edition: Focused mainly on how to write "template.yaml" and how to verify operations after deployment
This time, being the Implementation Edition, we will proceed with the Lambda function implementation in Python.
The code implemented in this article is available in the following repository:
2. Preparation
This article assumes the following:
- You have an AWS environment
- Python is used for the Lambda function implementation
- [Optional for Implementation Edition] AWS SAM environment setup is completed
- [Optional for Implementation Edition] Preparation for using AWS SAM CLI
■ Directory Structure
We will proceed with the following directory structure in this article:
Parent directory
┣ samconfig.toml ← Created in the Deployment Edition
┣ template.yaml ← Created in the Deployment Edition
┣ common_layer
┃ ┗ requirements.txt ← Created in the Implementation Edition
┗ s3_lambda_functions
┗ lambda_function.py ← Created in the Implementation Edition
■ Libraries
Here, I will explain the libraries that are prerequisites for the implementation.
The libraries used this time are as follows.
Libraries marked with ★ are essential for Lambda implementation.
| Library | Description |
|---|---|
| ★json | Essential for handling responses within the Lambda function. |
| ★aws-lambda-powertools | A library that assists with implementation in Lambda. |
| ★boto3 | A library for operating various AWS services. |
| urllib | Used to decode character codes. |
Creating requirements.txt
Prepare the libraries to be used in the Lambda function.
Define the introduced libraries as "requirements.txt" under "common_layer".
*Note: "json" and "urllib" are not needed as they are included by default.
aws-lambda-powertools==2.42.0 ; python_version >= "3.11" and python_version < "3.12"
boto3==1.34.151 ; python_version >= "3.11" and python_version < "3.12"
3. Implementation
Now, I will explain the implementation in the following order:
- Importing libraries
- Defining the logger
- Defining the main method
- Retrieving S3 information from the event
- Retrieving the uploaded file content using boto3
The full code is as follows:
Full code
import json
from urllib.parse import unquote_plus

import boto3
from aws_lambda_powertools import Logger

logger = Logger()


def lambda_handler(event, context):
    logger.info(json.dumps(event))

    # Bucket name
    bucket_name = event["Records"][0]["s3"]["bucket"]["name"]
    logger.info(bucket_name)

    # Object key
    object_key = unquote_plus(event["Records"][0]["s3"]["object"]["key"])
    logger.info(object_key)

    # ETag
    etag = event["Records"][0]["s3"]["object"]["eTag"]
    logger.info(etag)

    # Size
    size = event["Records"][0]["s3"]["object"]["size"]
    logger.info(size)

    # Retrieve the content of the file uploaded to S3
    s3_client = boto3.client("s3")
    response = s3_client.get_object(Bucket=bucket_name, Key=object_key)
    file_content = response["Body"].read()
    logger.info(file_content)
■ Step 1: Importing Necessary Libraries
First, import the necessary libraries.
import json
from urllib.parse import unquote_plus

import boto3
from aws_lambda_powertools import Logger
■ Step 2: Defining the Logger
Next, define the "logger" imported from "aws_lambda_powertools".
By defining the "logger," you can output logs to the CloudWatch logs of the Lambda function.
logger = Logger()
■ Step 3: Defining the Main Method
Let's move on to implementing the main method.
Regarding how to write the method definition, the following format is the standard boilerplate syntax.
def lambda_handler(event, context):
| Argument | Description |
|---|---|
| event | Data that serves as the argument when the Lambda function is called. In this case, information about the file uploaded to S3 is provided. |
| context | Contains information about the execution environment of the Lambda function. It will not be used this time. |
■ Step 3: Extracting Uploaded File Information from the event
Next, extract the information of the uploaded file from the "event".
The "event" provided as an argument is given in JSON format like the following.
Image of the event content
{
    "level": "INFO",
    "location": "lambda_handler:11",
    "message": {
        "Records": [
                "s3": {
                    "s3SchemaVersion": "1.0",
                    "configurationId": "Dummy",
                    "bucket": {
                        "name": "lambda-bucket-20240919",
                        "arn": "arn:aws:s3:::lambda-bucket-20240919"
                    },
                    "object": {
                        "key": "public/test.txt",
                        "size": 23,
                        "eTag": "qawsedrftghyujikolp123456789",
                        "sequencer": "0123456789ABCDEFG"
                    }
                }
            }
        ]
    },
}
In a Lambda function, the basic approach is to write code that accesses each item in the JSON-formatted "event" as follows.
# Bucket name
bucket_name = event["Records"][0]["s3"]["bucket"]["name"]

# Object key
object_key = unquote_plus(event["Records"][0]["s3"]["object"]["key"])

# ETag
etag = event["Records"][0]["s3"]["object"]["eTag"]

# Size
size = event["Records"][0]["s3"]["object"]["size"]
*Note: "unquote_plus" is used only for the object key. This is because if the uploaded filename contains characters like Japanese, it will be retrieved as character codes (e.g., "%E3%81%82"). Using "unquote_plus" converts the character codes back into the correct string.
■ Step 4: Using Boto3 to Retrieve the Uploaded File Binary
Finally, let's try to retrieve the binary of the uploaded file using "boto3".
First, define the boto3 client and provide the AWS service name (S3) as an argument.
s3_client = boto3.client("s3")
Now, let's actually operate boto3.
To retrieve objects stored in S3, you can use the "bucket name" and "object key" as arguments in the following format.
response = s3_client.get_object(Bucket=bucket_name, Key=object_key)
Although it cannot be confirmed during the implementation phase, the response outputted to the logger is also in JSON format.
Image of the response content
{
    "level": "INFO",
    "location": "lambda_handler:32",
    "message": {
        "Body": "<botocore.response.StreamingBody object at 0xffff813ab820>"
    },
}
The file information uploaded to S3 is stored in the "Body" mentioned above.
Therefore, we further retrieve the "Body" of the response as follows.
file_content = response["Body"].read()
Then, the file content is outputted in the "message" part as follows.
Image of the body content
{
    "level": "INFO",
    "location": "lambda_handler:34",
    "message": "Uploaded file content",
    "service": "S3Application",
}
5. Conclusion
In this article, I explained the implementation steps for a serverless application that executes a Lambda function triggered by a file upload to S3 and retrieves the content of that uploaded file.
With this implementation, you can easily build a workflow where file content is processed by a Lambda function every time a file is uploaded to S3.
In the next "Deployment Edition," I will explain in detail the steps to deploy the Lambda function to the AWS environment, how to write the configuration file, and how to verify operations after deployment.
Supplement
■ How to Set S3 Trigger for a Lambda Function
I will introduce how to add a trigger to a Lambda function without using template.yaml.
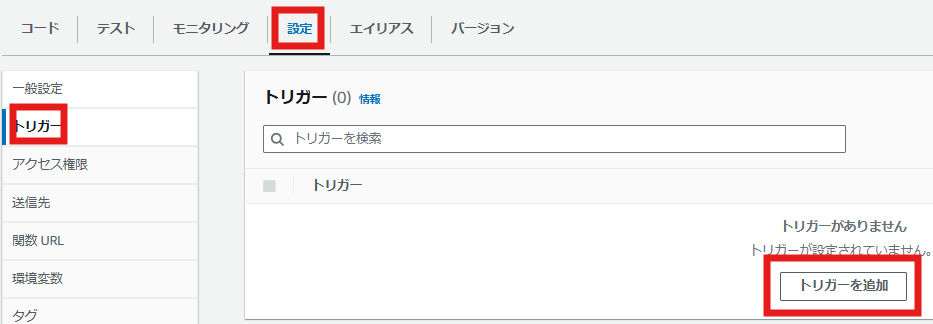
In the AWS Management Console, navigate to "Lambda → Functions → [Target Lambda Function]."
From the "Configuration" tab, click "Add trigger."
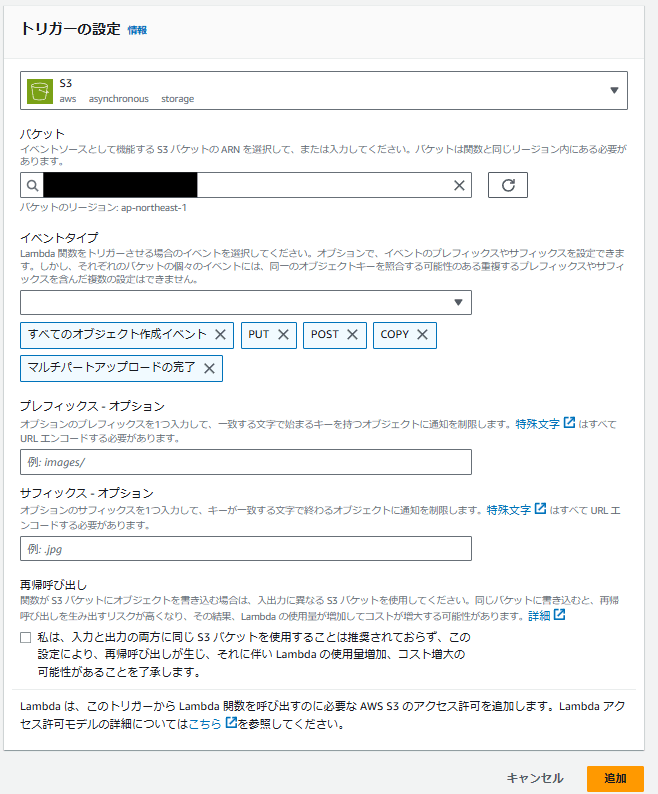
Configure it as follows and click "Add."
- Source: S3
- Bucket: Any bucket
- Event type: All object create events
- Recursive invocation: Check the box
Discussion